Every top model.
One key.
Claude, GPT, GLM, DeepSeek, Grok and more behind a single OpenAI- and Anthropic-compatible API. Plug it into the tools you already use, pay per token, top up with crypto.
- No subscription
- Prompts never stored
$ ▍
 GPT-6 Astra−95%
- GPT-6.1 Sol−95%
- GPT-6 Sol−92%
- GPT-6 Luna−50%
- GPT-5.6 Sol−88%
- GPT-5.6 Terra−80%
- GPT-5.6 Luna
- GPT-5.5−92%
 Claude Fable 5−95%
- Claude Sonnet 5−77%
- Claude Opus 4.6−91%
- Claude Opus 4.7−91%
- Claude Opus 4.8−91%
- Claude Opus 5−91%
- Claude Opus 5.5−80%
 GLM-5.2−90%
- GLM-5.3−90%
- GLM-5.3 Uncensored
- GLM-5.3 Flash−57%
- GLM-5.3 Flash Uncensored
- GLM-5.3 Flash Abliterated
 DeepSeek V4.1 Flash−84%
- DeepSeek V4 Flash−77%
- DeepSeek V4 Pro−49%
 Grok 4.7−93%
- Grok 4.6−93%
- Grok 4.5−93%
 MiMo V2.6 Pro
- MiMo V2.6 Flash
 Kimi K3
- DeepSeek V4 Pro Uncensored
- Claude Sonnet 5.5
- GLM-5.3 Abliterated
 Gemma 4 31B Abliterated
- Claude Haiku 5.5
- Gemini 4 Argon
- QWQwen3 Uncensored
- QWQwen3 Abliterated
- DeepSeek V4.1 Flash 1017
- DeepSeek V4.1 Flash 1017 Abliterated
- Kimi K3.1 Pro
- DeepSeek V4.1 Flash Abliterated
- Claude Opus 5.5 Max
- DeepSeek V4.1 Flash Abliterated Fast
- Claude Fable 5.2
Built for people who ship with agents
Coding agents burn through tokens and swap models constantly. We made the plumbing boring so you can stay in flow.
One key, every model
Switch between Claude, GPT, GLM, DeepSeek and others by changing a single string. No separate accounts, no separate bills, no waitlists.
Both wire formats
OpenAI Chat Completions & Responses, and Anthropic Messages — streaming, tools and reasoning pass through untouched.
Cache-aware billing
Cached prompt tokens are billed at the cache price, often ~10× cheaper. Agents re-send context all day — you keep the savings.
Every request, itemised
Model, input, output and cache tokens, latency and exact cost for each call — live in your dashboard.
Top up with crypto
USDT, USDC, BTC, ETH and more. Credited automatically after one confirmation. No card, no KYC forms.
How it works
- 01
Get your key
Sign in with Telegram — you get an API key instantly.
- 02
Point your tool at us
Set the base URL and key in Claude Code, OpenCode, Cursor… We generate the exact config for you.
- 03
Pay only for tokens
Top up with crypto when you like. Usage is deducted per request, with a full breakdown.
Images too, from about one cent
FLUX, Google Nano Banana and Recraft with the same account and balance. Create images on the website, in the Telegram bot, or through the OpenAI-compatible API.
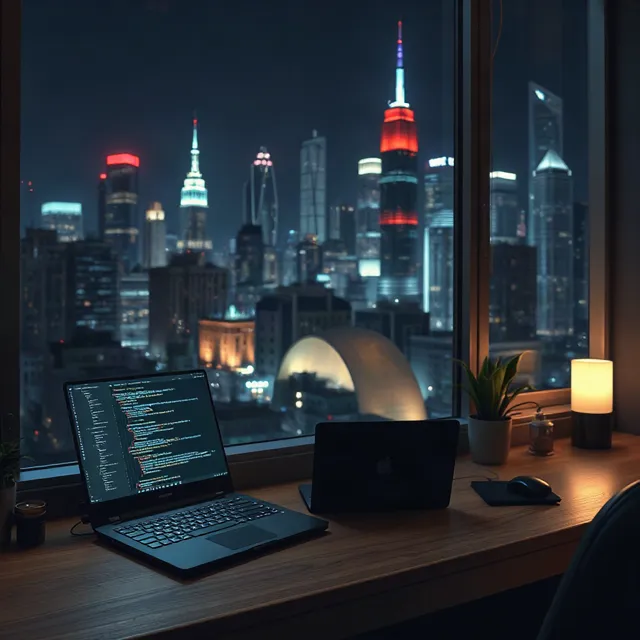
Fast and cheap: drafts, ideas, lots of variations.
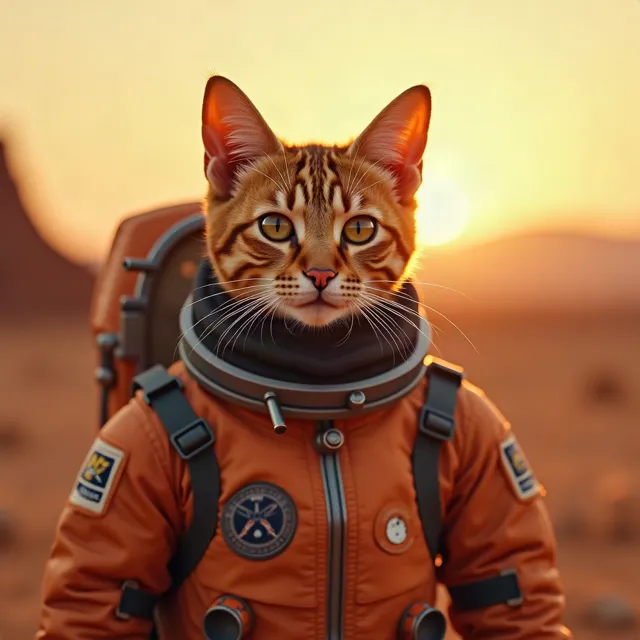
High quality photos and art, follows prompts closely.
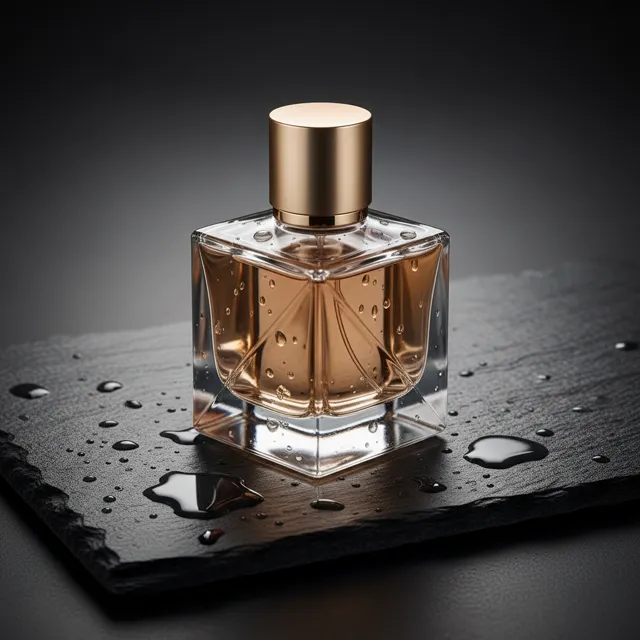
Google's image model: realistic, great at scenes and products.
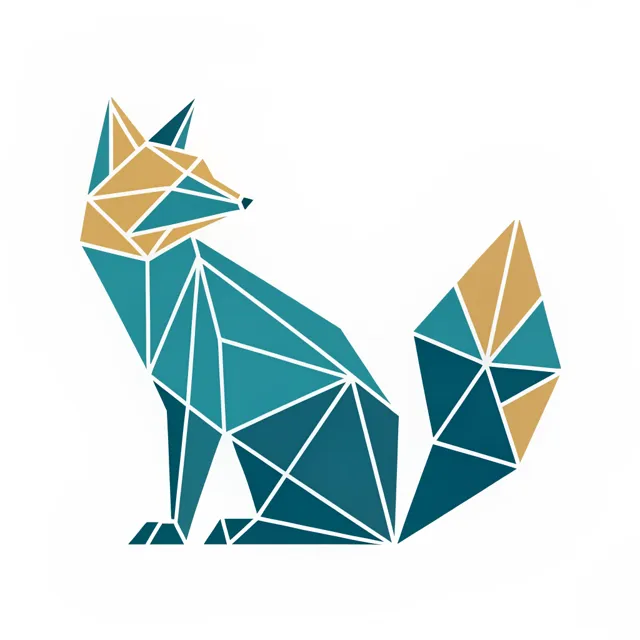
Design style: logos, posters, illustrations, clean text.
Drop-in for the tools you already use
If it accepts a custom base URL, it works. Pick your tool in the docs or the bot and copy a ready-made config with your key already inside.
The official models, up to 95% cheaper
Genuine Claude, GPT, GLM, DeepSeek and Grok models, billed per token below each provider's own API price. Cached input is billed at the cache rate automatically.
−95%vs official- Context
- 1.05M
- Input
- $0.90
- $10.00
- Output
- $0.90
- $50.00
−95%vs official- Context
- 1M
- Input
- $0.90
- $10.00
- Output
- $0.90
- $50.00
−90%vs official- Context
- 1M
- Input
- $0.20
- $1.40
- Output
- $0.20
- $4.40
−49%vs official- Context
- 1M
- Input
- $0.50
- $0.66
- Output
- $0.50
- $1.98
GPT-6 AstraOpenAI$20.00 $0.90−95%Claude Fable 5Anthropic$20.00 $0.90−95%GLM-5.2Zhipu GLM$2.15 $0.20−90%DeepSeek V4 ProDeepSeek$0.99 $0.50−49%Official = the provider's published API price (standard tier). See each model's page for the source.
Which tools work with it?+
Anything that lets you set a custom base URL: Claude Code, OpenCode, Cline, Roo Code, Cursor, Continue, Codex CLI, the OpenAI and Anthropic SDKs, LangChain, LiteLLM and plain curl. The dashboard and the Telegram bot generate ready-to-paste configs with your key filled in.
Is it OpenAI- or Anthropic-compatible?+
Both. Use /v1/chat/completions or /v1/responses with OpenAI clients, and /v1/messages with Anthropic clients. Streaming, tool calling and reasoning parameters are passed through unchanged.
How am I billed?+
Pay as you go, per token. Input, output and cached tokens are metered on every request and deducted from your prepaid balance in real time. You can see every request, its tokens and its cost in your dashboard. No subscription, no monthly minimum.
Do cached tokens cost less?+
Yes. When a model re-uses a cached prompt, those tokens are billed at the much lower cache price — usually around a tenth of the normal input price. Coding agents re-send long contexts, so this adds up quickly; your usage page shows the savings.
How do I pay?+
Top up your balance with crypto — USDT, USDC, BTC, ETH, LTC and more across several networks. Your balance is credited automatically after one blockchain confirmation.
Is there a free trial?+
New accounts get a small trial credit to test selected models, valid for a limited time (usually 72 hours). Top up any amount to unlock every model and higher rate limits.
Do you store my prompts?+
Not for API requests. We only record metadata needed for billing — model, token counts, cost, latency and status. Prompt and response content of API requests is never stored (Chat page history: see Privacy).
What happens if my balance runs out?+
A request that has already started always finishes. New requests are refused with a clear 'insufficient balance' error until you top up — you're never charged beyond what you've prepaid by more than one request.
Your agents, every model, one bill.
Get a key in seconds. Top up any amount to start.