AI Agents in Production: Why Independent Approvals Can Trigger Outages
Autonomous agents operating production workloads can cause outages by consuming the same redundancy. Here is how shared disruption reservations solve the problem.
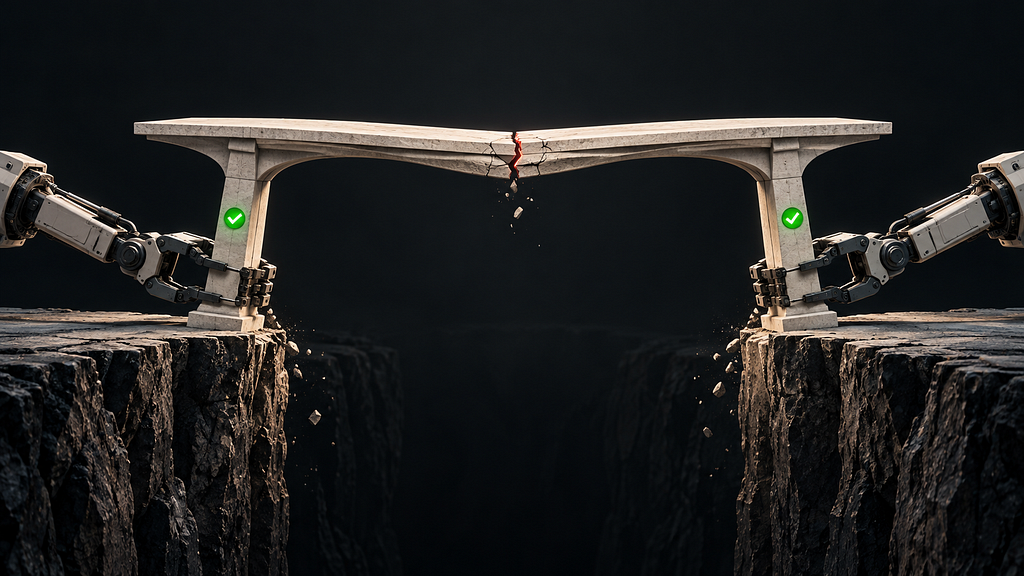
As engineering teams delegate infrastructure management to autonomous agents, a subtle architectural risk emerges: two separate automated systems can execute individually safe, fully approved actions that together trigger a complete system outage.
Consider an infrastructure setup where a payment service is divided between a virtual machine and a Kubernetes cluster during a migration phase. Both environments are operational, and either can support the workload independently. An infrastructure agent inspects the system, confirms that Kubernetes is healthy, and initiates a routine VM reboot. At the same time, a deployment agent checks that the VM is functioning and begins a stop-and-start release on Kubernetes. While each agent possessed valid credentials, verified existing health, and acted within its boundaries, both relied on the exact same redundancy. With both actions running simultaneously, neither backend can process payments.
The concurrency trap in agent execution
This failure pattern mirrors classic write skew in database systems, where separate transactions read identical data, modify distinct records, and inadvertently produce an invalid state that violates global constraints. In infrastructure, checking system health independently gives both agents a valid reason to proceed because monitoring data reflects the present rather than upcoming actions.
Existing mechanisms offer incomplete protection against this issue. In Kubernetes, PodDisruptionBudgets can control voluntary evictions, but they do not manage external virtual machines, nor do they natively govern rolling updates for Deployments or StatefulSets.
The challenge becomes more pressing as enterprises scale access for automated tools. For instance, Uber Engineering’s MCP Gateway hosts more than 800 MCP servers and 5,000 tools, using registries, scoped permissions, and data redaction to manage access. However, credential scoping and authorization only resolve whether an agent is allowed to execute a command; they do not evaluate whether that change can safely happen right now alongside other automated operations.
Coordinating changes through disruption reservations
To prevent conflicting updates, automation systems must introduce a coordination layer centered on disruption allowances. Before any disruptive action begins, an agent must atomically reserve the right to affect a given service's capacity.
Under this model, an admission rule dictates that after factoring in active reservations and the requested update, at least one verified backend capable of serving current traffic must remain operational. If the VM maintenance task is admitted first, it records a durable reservation. Even if the VM still appears healthy during the early seconds of the process, any subsequent deployment request targeting Kubernetes will be rejected or placed on hold because the service’s allowance has already been claimed.
This coordination requires several foundational practices:
- Atomic evaluation: Checking existing impact and claiming the reservation must happen in a single atomic transaction, such as using PostgreSQL row-level locks, to eliminate race conditions.
- Post-action verification: The reservation cannot simply release when a command exits successfully. The coordinator must keep the reservation active until health checks confirm the altered backend is genuinely ready to serve live traffic.
- System topology mapping: Relying on static lists is fragile during deployments. A compiled system graph connecting VMs, containers, load balancers, and dependencies helps determine which shared conditions are affected by a proposed change.
- Condition-bound approval: Approvals must be tied to specific environmental states. If the supporting conditions change between approval and execution, the executor must refresh its evidence or halt.
What it means for developers
For engineers designing agentic pipelines, autonomy requires designing for concurrency rather than treating agents as isolated scripts. Systems should not assume that valid credentials and clean health checks guarantee a safe deployment.
Developers must build explicit execution coordinators that treat application availability as a shared, lockable state. When modeling multi-agent workflows, test scenarios must verify what happens when two workers propose changes simultaneously and confirm that active reservations survive unexpected agent crashes or network disconnects.
For teams experimenting with autonomous agents to handle multi-step workflows, developers can try top AI models cheaply through one API at https://apixoai.online to evaluate different reasoning capabilities against complex coordination logic. Ultimately, giving software the authority to modify production requires the software to coordinate its disruptive impact, ensuring that one automated plan never consumes the redundancy another plan depends on.
Source: The Next AI Outage Could Begin With Two Approved Changes — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key