AI Agents Write Blender Code for 3D Scenes but Fail at Self-Evaluation
Researchers introduce LEGO-Anything and LEGO-Bench to evaluate how AI agents construct 3D Blender scenes from photos, highlighting key spatial reasoning flaws.
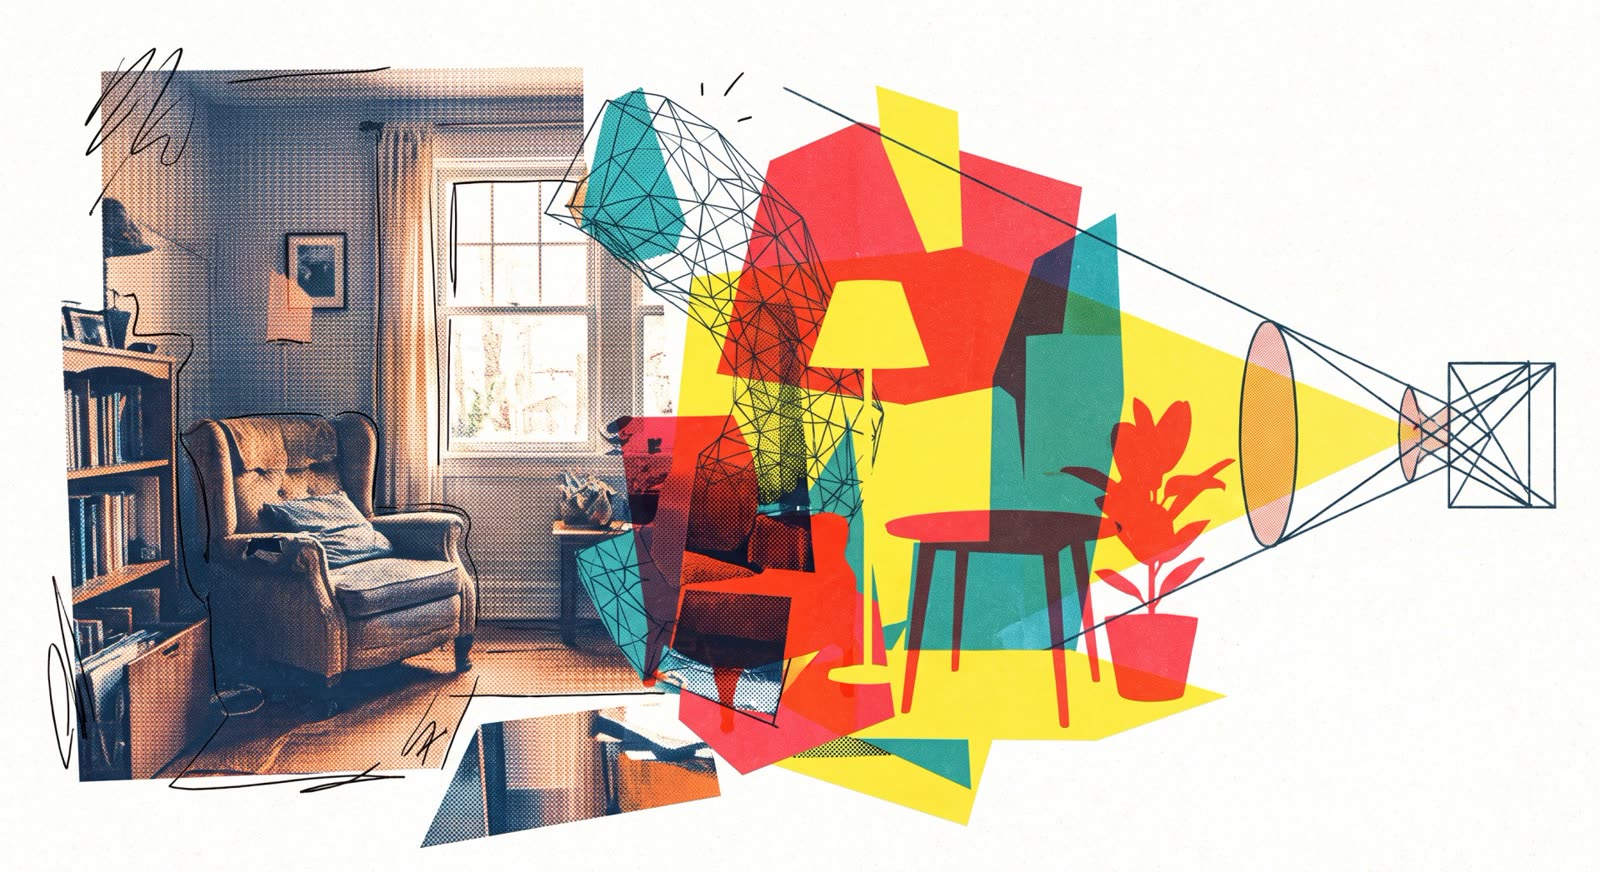
Researchers have introduced an approach called Image-to-Code, embodied in a framework named LEGO-Anything, where a coding agent generates an executable Blender program starting from a single photograph. Instead of attempting a complete scene render in a single pass, the agent operates iteratively by drafting code, executing it inside the Blender 3D software, analyzing the output image, and refining the program until it reflects the original photo. Because the resulting artifact is standard code, attributes such as geometry, camera positions, object definitions, and scene layouts are explicitly captured and can be run, checked, or modified like any conventional program.
How LEGO-Bench exposes model limits
To evaluate these agent outputs against accurate spatial data, researchers created LEGO-Bench. Real-world photos lack precise 3D ground truth measurements, whereas simple synthetic images fail to provide realistic visual details. To solve this, LEGO-Bench utilizes 208 images derived from 104 indoor and outdoor simulator scenes, employing 443 registered assets. This setup hides exact depth, geometry, and asset assignments to act as an automated answer key while maintaining natural visual representations. LEGO-Bench measures models across validity, geometric accuracy, and visual appearance via pixel-by-pixel reference comparisons.
Testing across six GPT configurations revealed that while all models consistently generated working scene code, actual geometric precision varied significantly. The top-performing model, GPT-6 Astra, achieved accuracy scores of 53.4 percent on indoor scenes and 39.6 percent on outdoor scenes, whereas weaker configurations scored around 15 percent. Expanding the models' reasoning budget yielded notable performance gains; for instance, GPT-6 Astra's accuracy on an office test subset rose from 32.3 percent to 61.8 percent.
However, detailed step analysis highlighted severe flaws in agent self-assessment. Agents frequently made poor initial coding decisions or executed regressive edits that destroyed previous progress. In one instance, GPT-6 Astra lowered its scene accuracy from 33.9 percent to 4.4 percent late in its refinement process. When tasked with choosing between two scene variations, models evaluated geometric correctness at or below chance level, proving that AI agents struggle to accurately judge whether their edits improve 3D alignment.
Concrete metrics and downstream tasks
To address this evaluation gap, researchers developed LEGO-Plugin, an extension that requires no additional training. The plugin anchors the initial scene to the reference photograph, replaces subjective model self-judgment with objective spatial measurements, and prevents regressive code edits from overwriting valid progress. Applying LEGO-Plugin improved all six tested configurations. Weaker agents experienced the largest performance increases, rising by up to 62.7 percent, while GPT-6 Astra gained approximately two percentage points.
Researchers also evaluated whether reconstructed executable code could support downstream computer vision tasks without dedicated model training. Because the scenes exist as code, object detection, depth estimation, and segmentation can be extracted directly. The reconstructed scenes yielded usable results: object detection reached roughly half the performance of the specialized model DINO, while gaps remained larger against specialized tools like SAM 3 for segmentation and Depth Anything 3 for depth estimation.
The broader landscape shows growing interest in spatial AI agents. AI researcher Yoav Artzi noted GPT-6 Astra's performance lead, suggesting it was trained on extensive 3D Blender datasets. Concurrently, 3D engine creators like Unity have published official plugins for Codex and Claude Code. Other projects take different paths: World Labs' Atlas model skips explicit code generation to build 3D environments directly, while Google DeepMind's GenCeption uses video models for depth and segmentation to match specialized tool performance.
What it means for developers
For software engineers working at the intersection of AI and computer graphics, the Image-to-Code paradigm demonstrates both the capabilities and limits of modern LLM agents. While current models excel at writing syntactically valid Blender code, their inability to evaluate spatial geometry means agents cannot reliably refine complex 3D structures without external feedback loops.
Developers building 3D agent workflows should avoid relying on an LLM's self-evaluation to verify output quality. Integrating objective metric checks, program guardrails, or targeted extensions like LEGO-Plugin is essential to prevent models from destroying valid work during iterative cycles. Furthermore, developers experimenting with spatial reasoning or comparing code-generation performance across models like GPT-6 Astra, Claude, or Gemini can try top AI models cheaply through one API at https://apixoai.online.
Although current executable 3D outputs do not yet match specialized vision models like DINO, SAM 3, or Depth Anything 3, code-based scene representation offers developers a flexible foundation. Because the output is standard executable code, developers can programmatically extract geometry, camera angles, and object tags, paving the way for hybrid workflows that blend deterministic code execution with LLM reasoning.
Source: AI agents build 3D scenes from photos but have no idea if they got it right — The Decoder. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key