AutoSynthData Automates Training Data Generation for Enterprise AI Agents
Discover AutoSynthData, a new framework that turns target model failures and teacher successes into validated training data for enterprise AI agents.
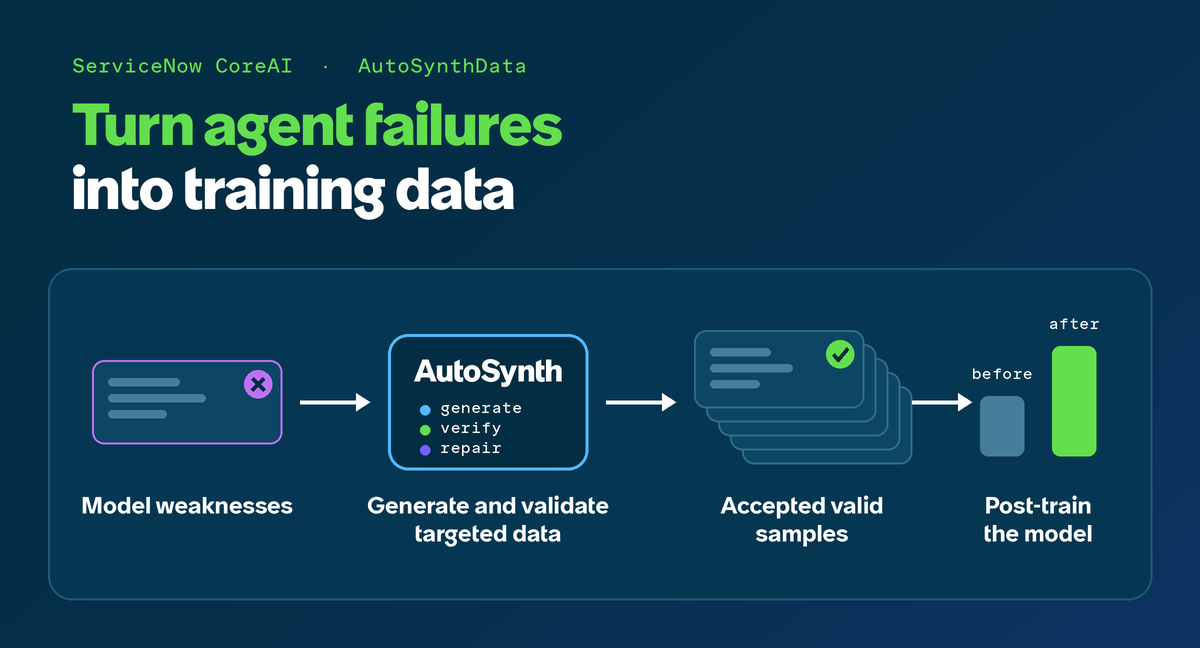
Deploying artificial intelligence agents within specific corporate environments often highlights capability gaps. While a model may possess broad intelligence, it can struggle with customized workflows, specific tool combinations, or strict system constraints. Addressing these limitations requires extensive training data that accurately reflects real-world scenarios while exercising the precise weaknesses of the model. ServiceNow CoreAI has introduced AutoSynthData to automatically convert capability gaps into targeted training tasks.
AutoSynthData operates by analyzing where a target model fails in an environment and leveraging a stronger teacher model to understand successful execution paths. The framework dynamically establishes a curriculum that shifts as the target model improves, focusing continuous training on remaining weaknesses. The overall structure of a generated task relies on a clear abstraction comprising a system specification, a user prompt, and a verifier. These tasks must fulfill three essential conditions: feasibility, realism, and appropriate difficulty.
What it means for developers
For developers building stateful enterprise agents, generating clean synthetic training data can be a major bottleneck. AutoSynthData addresses this by separating generation controls from environment execution, utilizing parallel target generation and a multiplication phase to scale datasets securely. Developers looking to experiment with advanced capabilities can try top AI models cheaply through one API at https://apixoai.online. Every candidate task in the pipeline undergoes rigorous sample-level verification, including positive and negative gates alongside a structured critique and repair loop, ensuring that poor verifiers or broken trajectories are filtered out before fine-tuning begins.
Rigorous Verification and Batch-Level Review
Generating plausible requests is insufficient for effective model training. AutoSynthData evaluates candidates to confirm they are executable and that their reference solutions function correctly. Positive verification ensures the intended solution satisfies the generated task, while negative verification confirms that incorrect outcomes fail appropriately. If a candidate fails these checks, a critic module diagnoses the issue for targeted repair rather than discarding the entire generation process from scratch.
Beyond individual samples, the framework performs batch-level reviews to monitor dataset coverage and diversity. Meta-reviews track overrepresented task families and missing capability dimensions, allowing controllers to redirect generation effort where it is most needed.
EnterpriseOps Gym Experiments
To measure its effectiveness, the pipeline was tested using EnterpriseOps Gym in Hybrid and ITSM environments. In the Hybrid evaluation using Gemma-4-26B-A4B-it as the target model and Qwen3.8-27B as the teacher, AutoSynthData produced 2,000 synthetic samples in roughly 18 hours. Fine-tuning the target model on this dataset improved mean Pass@1 by 7.2 percentage points—a 35% relative enhancement—while closing 59% of the initial gap between the target and reference models. A secondary run in the ITSM domain utilized DeepSeek-V4.1-Flash as a teacher to generate nearly 2,000 samples, demonstrating that closing the loop between model evaluation, task generation, and post-training can significantly elevate agent performance in controlled enterprise settings.
Source: AutoSynthData: Generating Training Data for Enterprise Agents — Hugging Face blog. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key