Building High-Volume AI Pipelines With Claude Haiku 5.5 and Work Queues
Learn how to structure Claude Haiku 5.5 pipelines using bounded work queues, deterministic acceptance gates, and clear escalation rules for high-volume tasks.
When cheaper and faster artificial intelligence models hit the market, engineering teams often face an unexpected challenge: the cost of running inference drops so low that routine supervision disappears. A system previously constrained by latency and expense suddenly handles thousands of incoming extractions, categorizations, and ticket classifications. Claude Haiku 5.5 is tailored for this kind of high-volume, repetitive workload—handling compaction, triage, document parsing, and scoped subagent routines while Anthropic positions its larger models for complex agentic programming. However, sending unconstrained volume through a lightweight model without strict boundaries frequently leads to silent errors downstream.
Building a reliable high-throughput pipeline requires shifting from dynamic model routers to structured work queues equipped with clear stop rules. Instead of asking which model should read an open-ended prompt, an effective pipeline defines precisely which narrow tasks are safe for a fast model, what schema proves success, and what fallback must run when verification fails.
Replacing model routers with bounded work queues
A robust queue setup starts by turning free-form user inputs into immutable task packets. Instead of telling a model to resolve an ambiguous problem, the packet narrows the assignment to an objective deliverable, such as extracting fields according to a strict schema or selecting a label from an established taxonomy. The task packet holds only the necessary context, references, and limits, stripping away broad permissions to modify state or exercise open-ended discretion. Enforcing idempotency through distinct job IDs ensures that repeated tasks never duplicate actions or writes.
Crucially, downstream acceptance cannot rely on whether a model appears confident. Work belongs in the fast Haiku lane only if code can deterministically verify the outcome. A validation gate inspects the response across three distinct criteria: schema compliance, factual grounding, and business logic. The system checks whether returned fields match expected formats, verifies that cited evidence spans exist word-for-word in the source data, and routes high-consequence categories to additional review. Code retains final authority over whether an output moves forward.
The three-step escalation ladder
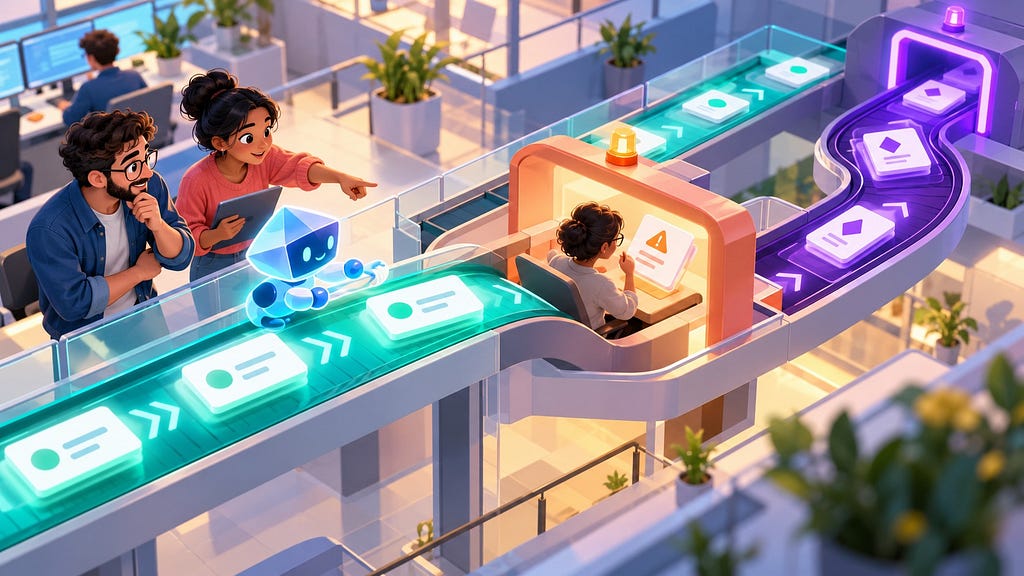
When a fast worker cannot cleanly settle an issue, the pipeline should follow a clear three-stage escalation path rather than looping through identical retries:
- Acceptance: If the output satisfies every programmatic test and carries low operational risk, the result is saved alongside the model version, policy ID, and approval reason.
- Deeper reasoning: If the output violates schema constraints, lacks required evidence, or exceeds execution deadlines, the system hands the work to a more capable reasoning model. Rather than starting from scratch, the packet includes the fast model's attempt and the specific validation errors encountered.
- Human escalation: Actions involving policy exemptions, irreversible changes, or sensitive routes skip automated approval entirely and require operator sign-off.
This design clearly separates retries from escalations. Retries exist exclusively to fix transient networking or infrastructure issues, whereas escalations handle task ambiguity and model uncertainty. Preserving failed attempts provides vital telemetry, highlighting whether poor data sources, shifting vocabularies, or flawed task definitions triggered the handoff.
What it means for developers
Deploying Claude Haiku 5.5 in production calls for shifting core metrics away from raw cost per token toward verified completion rates. A low token expenditure offers little value if ungrounded answers create manual corrections or database corruption. Teams must monitor the false-acceptance rate, latency across percentiles, and costs per verified completion.
To design and validate these tiered pipelines, developers can try top AI models cheaply through one API at https://apixoai.online, simplifying the process of testing small fast-lane workers alongside heavier reasoning systems.
Implementation should begin in shadow mode, running Haiku alongside established production flows to evaluate decisions before turning on live execution. By establishing test fixtures that intentionally inject missing fields, unsupported claims, and malformed inputs, developers can confirm that the queue halts predictably on bad inputs. High-volume AI pipelines achieve reliability not by trusting small models with difficult decisions, but by enforcing rigid architectural boundaries that recognize when automated work must stop.
Source: Claude Haiku 5.5 Work Queues: Design High-Volume AI Pipelines That Know When to Stop — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key