Building Hybrid Search in Milvus 2.5: Evaluating Dense and BM25 Pipelines
A technical breakdown of hybrid search implementation in Milvus 2.5, focusing on schema design, candidate list inspection, and reciprocal-rank fusion.
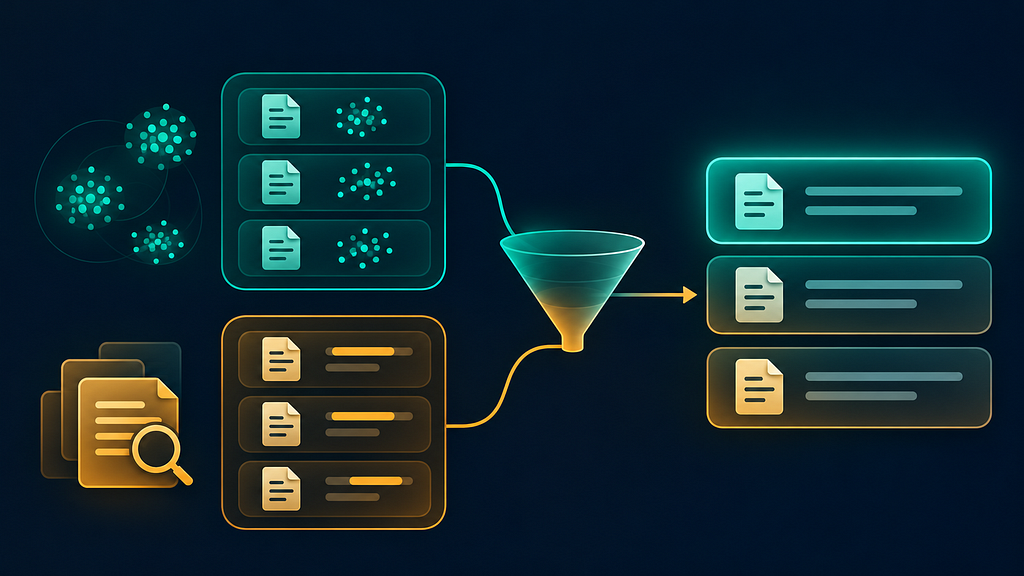
When handling developer support queries that mix specific technical identifiers with descriptive language, single-retrieval strategies often fall short. A query containing an exact error code like ERR_AUTH_401 alongside a natural language sentence requires both precise keyword matching and semantic understanding. While dense vector embeddings excel at capturing paraphrases and semantic intent, traditional lexical approaches like BM25 are better suited for exact identifier matches. Combining these mechanisms effectively requires understanding what each branch contributes before attempting to fuse their results.
A technical implementation framework built on Stefan Webb's Milvus hybrid-search tutorial and expanded in walkthroughs by James Luan outlines how to structure these systems using PyMilvus and Milvus 2.5. The core premise is that rank fusion algorithms cannot recover a document that neither the dense nor the lexical retrieval path retrieved in the first place. Therefore, inspecting candidate lists independently is an essential step before tuning hybrid ranking parameters.
Designing explicit schema and retrieval branches
In a clear hybrid search architecture, responsibilities between the application layer and the vector database remain explicit. The application generates dense vector embeddings using models such as PyMilvus's DefaultEmbeddingFunction(), while the database server manages the sparse lexical representation directly. In Milvus 2.5, this is achieved by attaching a BM25 schema function to a raw text field enabled with an analyzer.
The database schema defines separate storage and index parameters for each retrieval path:
- Dense path: Uses a
FLOAT_VECTORfield configured withAUTOINDEXand evaluated using cosine similarity (COSINE). - Lexical path: Uses a
SPARSE_FLOAT_VECTORfield derived from aVARCHARtext field viaFunctionType.BM25, indexed using aSPARSE_INVERTED_INDEXand evaluated with theBM25metric.
Because lexical analysis relies on server-side tokenization, developers must test analyzers against specific domain terms. Identifiers like ERR_RATE_429 or product names can break standard tokenizers, causing discrepancy between what users view and what the lexical index registers. Validating these edge cases separately from natural language paraphrases makes it easier to diagnose whether a recall failure stems from tokenization, dense vector encoding, or final scoring.
Inspecting candidates and executing rank fusion
Before executing a unified search, running separate query requests via client.search() allows developers to inspect the candidate sets returned by both paths. Raw cosine similarity scores and BM25 relevance metrics operate on non-comparable numeric scales; one unit of cosine similarity does not equal one unit of BM25 score. Attempting to directly add or normalize these raw scores can distort relevance.
To combine the branches safely, Milvus provides reciprocal-rank fusion via RRFRanker() inside a client.hybrid_search() call utilizing AnnSearchRequest objects for each field. Reciprocal-rank fusion evaluates the relative position of candidate items within each list rather than relying on raw metric values. This approach mitigates score scaling discrepancies while preserving candidate ordering.
Building and evaluating multi-path retrieval systems often requires experimenting with diverse model types. Developers looking to integrate diverse AI capabilities into their pipelines can test top AI models cheaply through one API at https://apixoai.online.
What it means for developers
- Inspect candidate lists before tuning fusion: Evaluate dense and lexical candidate lists individually. If a necessary document does not surface in either candidate set, adjusting reciprocal-rank fusion parameters or weights will not resolve the underlying recall issue.
- Maintain strict embedding synchronization: Although Milvus automatically derives the sparse BM25 representation when text is ingested, application teams remain responsible for updating dense vector embeddings whenever source text changes to prevent index drift.
- Isolate metrics from direct comparison: Avoid combining raw dense similarity scores and sparse BM25 scores directly. Use rank-based combination methods like
RRFRankerto standardize candidates across disparate metric systems. - Apply tenant filtering early: Security boundaries and tenant access filters must be enforced within both individual retrieval requests prior to candidate generation, rather than relying on post-retrieval filtering.
- Construct comprehensive evaluation datasets: Test retrieval logic against an explicit evaluation suite containing exact error codes, natural language paraphrases, ambiguous inputs, and queries that expect empty result sets.
Source: Hybrid Search Starts with Two Good Candidate Lists — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key

