Cohere Launches Embed 5 Family for Enterprise Search and RAG
Cohere has introduced Embed 5, a new embedding model family featuring Pro and Fast tiers, multimodal support, and a shared vector space for enterprise search and RAG workloads.
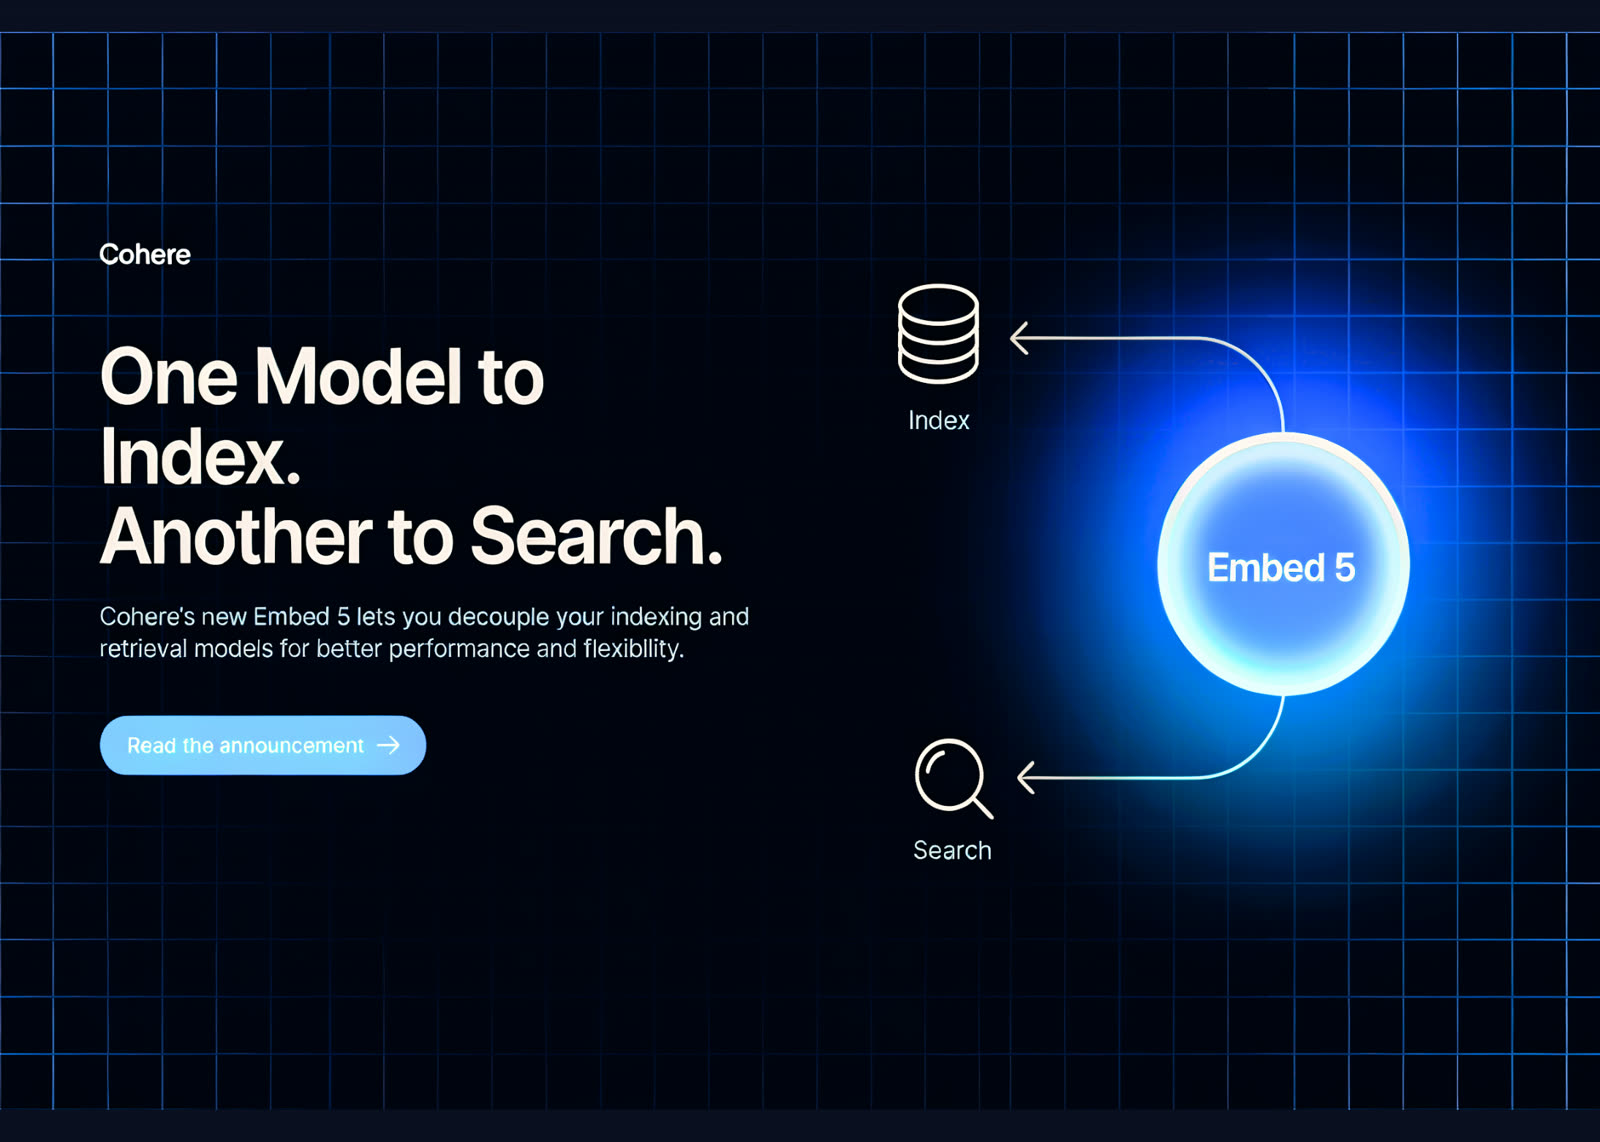
Cohere has launched its Embed 5 model family, engineered specifically for enterprise search, retrieval-augmented generation (RAG), and agentic retrieval workloads. The release includes two distinct tiers: Embed 5 Pro, which focuses on delivering maximum retrieval quality, and Embed 5 Fast, which is optimized to reduce latency and cost along live query paths.
Both tiers accept text, images, and fused text-plus-image inputs, handle over 100 languages, and support a maximum context length of up to 128,000 tokens. A notable architecture choice is that Pro and Fast share a single embedding space, allowing systems to index documents with one tier and query them using the other, provided both employ the same output dimension.
Performance and Benchmarks
According to Cohere's tests using its new RCP-nDCG@10 metric, Embed 5 Pro achieved an average score of 85.8 on the ViDoRe V3 benchmark, outperforming competing models such as Voyage 4 Large at 83.7, Gemini Embedding 2 at 83.2, and OpenAI text-embedding-3-large at 75.5. The Fast variant scored 84.5 on the same benchmark.
In financial domain evaluations, Embed 5 Pro secured the top rank on FinanceBench (80.1), FinQA (90.0), and ViDoRe V3 Finance (85.0), while Fast ranked second across all three metrics. Multilingual evaluations showed mixed results; while Pro led European language averages at 77, Gemini Embedding 2 scored higher on nine out of ten additional languages tested, including Japanese, Arabic, Hindi, and Telugu.
For throughput, Embed 5 Fast processed 377.3 documents per second during testing, compared to 159.7 documents per second for the Pro tier. Pricing for text tokens is set at $0.12 per million for Pro and $0.08 per million for Fast, with image inputs priced at $0.40 per million tokens for both options.
What it means for developers
Developers building agentic workflows and search systems can benefit from the shared vector space design, implementing a recommended pattern where the corpus is indexed using Pro for quality and queried using Fast to reduce compounding latency. Furthermore, developers can try top AI models cheaply through one API at https://apixoai.online.
The models support variable output dimensions ranging from 256 to 2048, with 2048 as the default, and output formats including float, int8, and binary. Utilizing Matryoshka representation learning alongside lower-precision outputs allows storage requirements to drop significantly. For instance, shifting from a 2048-dimension float32 vector (requiring 8 KB) to a 1024-dimension int8 vector (requiring 1 KB) or a 256-dimension binary vector (requiring 32 bytes) can reduce raw vector storage substantially across large indexes.
Availability and Deployment
Both Embed 5 Pro and Fast are generally available through the Cohere API, Model Vault, Microsoft Foundry, and Amazon SageMaker. For private or on-premise requirements, serving is supported via vLLM in a private VPC.
Source: Cohere Releases Embed 5: How It Compares to Voyage 4 Large, Gemini Embedding 2, and OpenAI — MarkTechPost. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key