Jev AI Model Brings Structured Outputs to Fast Classification Tasks
TypeSafe AI released Jev, a specialized model designed for classification and scoring instead of generating free-form text. We look at tests, use cases, and what developers should know.
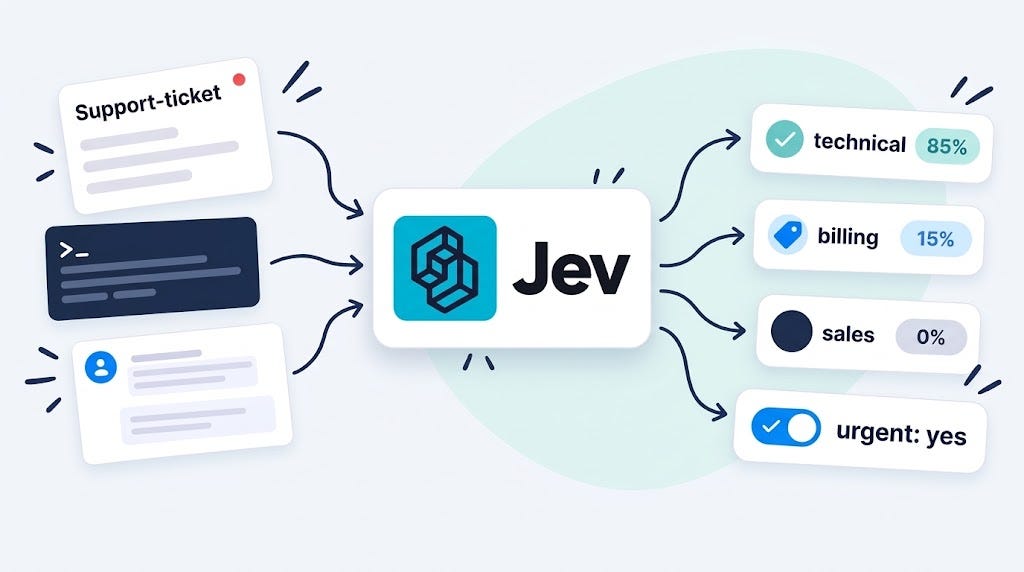
A startup called TypeSafe AI introduced a specialized model named Jev, designed to output structured numbers and probabilities rather than generating text word by word. Instead of drafting a response like a traditional large language model, Jev evaluates a situation and answers specific questions using predefined choices, scores, or yes-or-no criteria.
TypeSafe AI reports that a standard response takes between 70 and 500 milliseconds. The pricing is set at $0.042 per million input tokens, while output tokens are free because the system returns compact numerical data instead of long strings. Developers can define multiple questions in a single request, which are then evaluated in parallel to maintain low latency.
Capabilities and Independent Test Results
Jev supports three primary response formats: Choice for selecting an option from a list, Score for rating items on a defined scale, and Noul for binary yes-or-no evaluations. Every answer includes a confidence probability ranging from 0 to 1, allowing developers to route low-confidence cases to human reviewers or larger models.
Independent benchmarks and tests show varied results depending on the task. In an MLflow evaluation using 30 hand-labeled examples, Jev matched human judgments consistently with a median latency of 369 milliseconds. In a phishing detection test using synthetic emails, Jev initially lagged behind Claude Haiku on a single general prompt. However, when the task was broken down into five simpler questions, Jev reached 95% accuracy while remaining significantly faster and cheaper than comparable models.
Reviewers point out limitations as well. Jev struggles with math and coding tasks compared to reasoning-focused models. Furthermore, tests indicate that prompt injection attempts can alter a substantial portion of its outputs, meaning developers must implement proper input filtering and rely on English text, which the model handles best.
What it means for developers
For engineering teams handling high volumes of repetitive classification tasks, Jev offers a cost-effective alternative to larger LLMs. Common use cases include customer support routing, guardrails for flagging inappropriate inputs, filtering out irrelevant document search passages, and running automated evaluations at scale. Meanwhile, developers can also try top AI models cheaply through one API at https://apixoai.online.
Implementing Jev requires shifting logic back into application code by defining precise questions, valid options, and escalation thresholds in advance. Because the model operates in early access with a single region and evolving rate limits, developers should benchmark Jev against their own historical datasets before deploying it to production.
Implementation and Considerations
The model is accessed via Python and JavaScript SDKs using an environment variable for authentication. Developers interested in testing Jev can establish a baseline by running a few hundred historical cases through both Jev and their current model setup, comparing metrics such as price per thousand decisions, regional latency, and the percentage of automated handling versus human escalation.
Source: What Is Jev? What the Tests Show and Who Should Try It — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key