Mercor Reaches $20B Valuation to Scale Enterprise AI Agent Evaluation Infrastructure
Mercor has raised $750 million at a $20 billion valuation to expand its human-guided evaluation and training platform from frontier AI labs to enterprise environments.
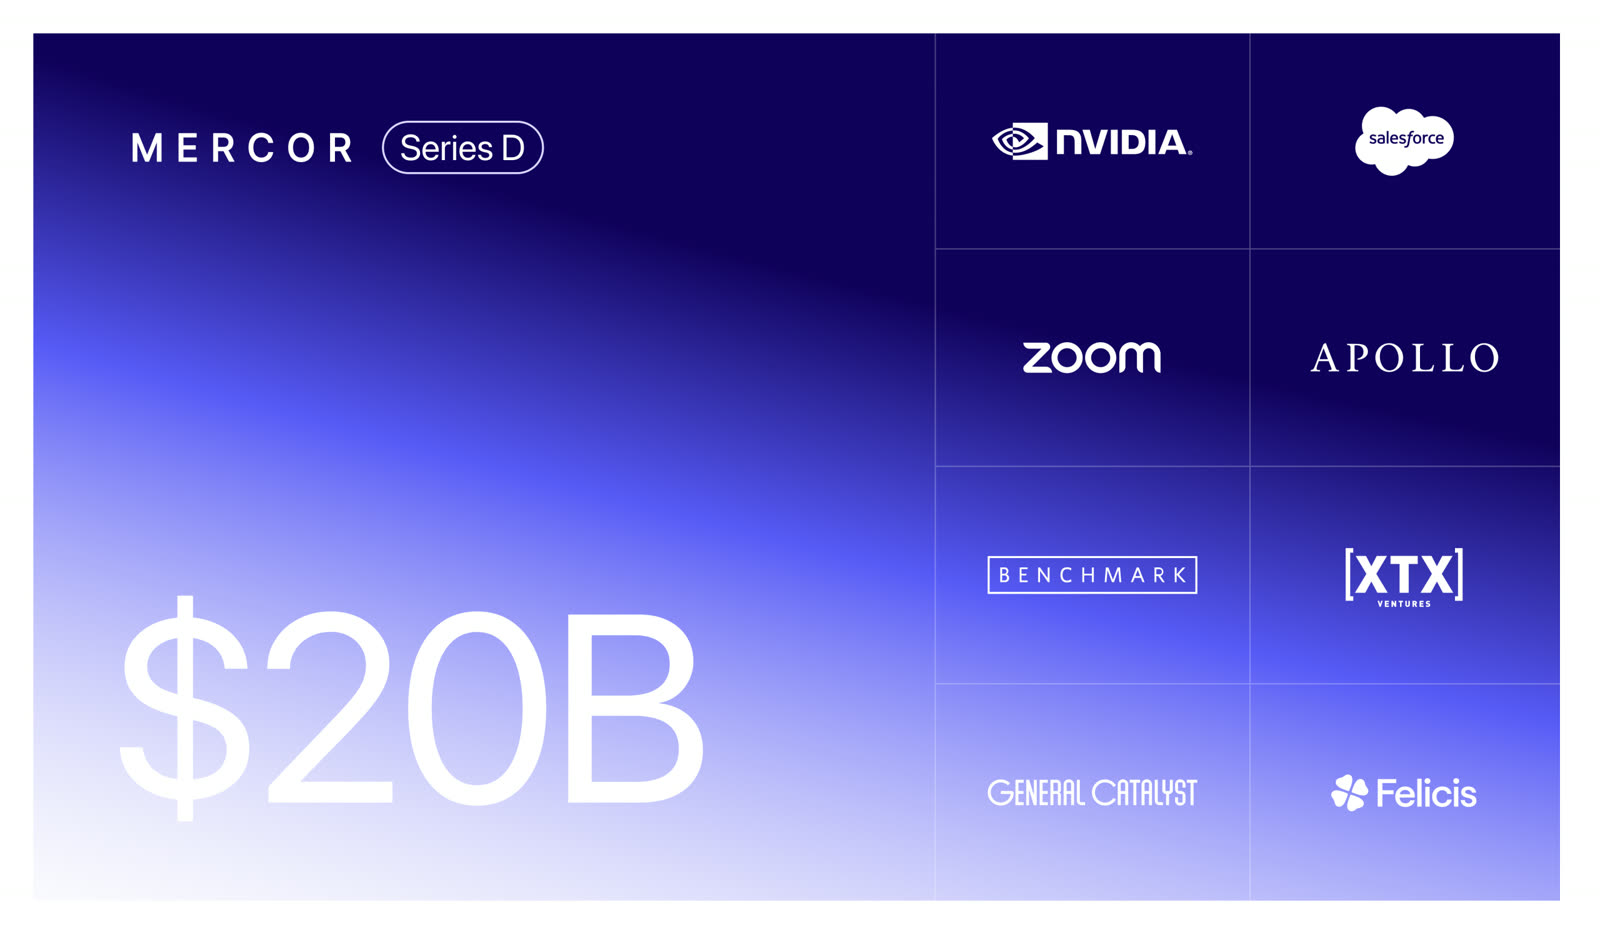
Training data and model evaluation platform Mercor.io Corp. has secured $750 million in new Series D funding, elevating its valuation to $20 billion. The company, which maintains a network of over 5 million subject matter experts to evaluate and fine-tune artificial intelligence systems, is shifting its focus from serving major frontier AI laboratories to providing customized evaluation infrastructure directly to corporate enterprises.
Co-Chief Executive Brendan Foody noted that every role across the economy will eventually require dedicated AI agents, making it essential for organizations to possess the infrastructure necessary to train and evaluate models against their internal workflows. Mercor spent the preceding two years developing its core testing framework alongside top-tier AI labs, a strategy that helped propel the firm's annualized revenue past $2 billion in June.
Custom Benchmarks for Enterprise Workflows
Standard public benchmarks frequently fail to reflect how an AI agent will handle real-world corporate environments. According to Mercor Co-Chief Executive Adarsh Hiremath, a model might achieve high scores on standardized public tests yet still stumble when confronted with the unique edge cases, software systems, and operational policies of a specific company.
To address this disconnect, Mercor constructs bespoke benchmarks tailored to each client's internal standards before commencing the post-training process. A critical component of this post-training infrastructure stems from Deeptune Inc., a New York-based startup that Mercor acquired in July. Prior to the acquisition, Deeptune spent two years replicating hundreds of enterprise software applications, providing simulated environments where AI agents can practice and refine their capabilities. Mercor plans to use its new capital to expand its research facilities and scale up these simulated testing environments.
Backed by Tech Giants and VCs
The $750 million investment round brought in notable corporate backers, including Nvidia Corp., Salesforce Inc., and Zoom Communications Inc. Previous investors Benchmark Capital Management Co., Felicis Ventures Management Co., and General Catalyst Group Management also participated. Additional funding came from Sapphire Ventures, StepStone Group Inc., XTX Ventures, Fundomo, G Squared Equity Management LP, Glade Brook Capital Partners, and funds affiliated with Apollo Global Management Inc.
This funding follows an October 2025 Series C round led by Felicis, which raised $350 million at a $10 billion valuation. The latest Series D transaction also incorporated a tender offer allowing employees to sell shares, though Mercor has not disclosed the precise division between liquidity and new balance-sheet capital. Jai Das, president and partner at Sapphire Ventures, pointed out that open-source models are becoming increasingly capable for enterprise deployments, positioning Mercor's hard-to-replicate evaluation platform as a key asset for businesses building specialized autonomous systems.
What it means for developers
For software engineers and AI builders, Mercor's massive valuation highlights a broader industry pivot from raw model capability toward rigorous, domain-specific evaluation. As autonomous agents take on higher-stakes tasks inside enterprise software, developers can no longer rely purely on general leaderboard statistics to gauge whether a model is production-ready.
Instead, building trustworthy enterprise agents requires testing systems directly against realistic business environments, software integrations, and strict compliance rules. As developers work to benchmark and integrate various foundation models into their agentic workflows, services like Apixo offer a practical way to test and query top AI models cheaply through one API at https://apixoai.online.
This shift means developers will increasingly need to incorporate custom evaluation loops and simulated sandbox testing into their deployment pipelines. As open-source and proprietary models proliferate, the primary engineering challenge moves from prompt tuning to continuous evaluation—ensuring that agents act predictably when executing complex tasks within corporate software ecosystems.
Source: Mercor raises $750M at $20B valuation to take AI agent evaluation to enterprises — SiliconANGLE AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key

