New Research Highlights Trust Gaps and Protocol Pivoting Vulnerabilities in AI Agents
Recent security findings reveal how trust assumptions in the Model Context Protocol allow malicious prompts to spread between AI agents.
As organizations increasingly deploy autonomous AI systems across millions of networks, security researchers have uncovered critical structural flaws in how these programs communicate. Over the past five months, Google and four other diverse organizations have acknowledged vulnerabilities that allow an attacker to leverage one internal agent to propagate harmful instructions to others. This discovery sheds light on hidden security gaps within modern agentic architectures, particularly concerning standard communication frameworks.
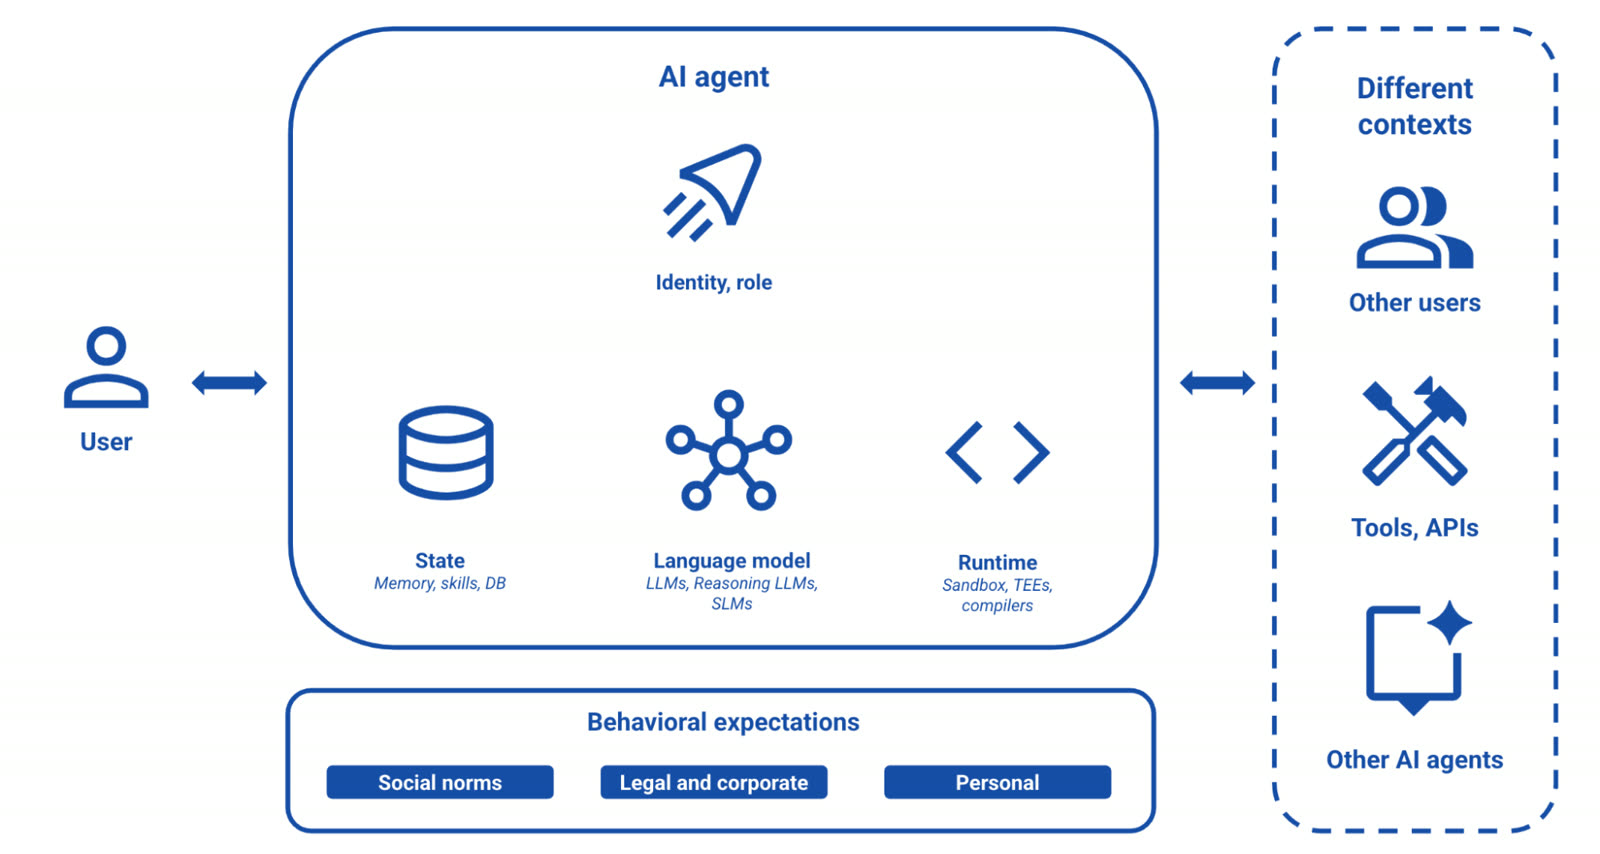
Independent researcher Syed Anas Mohiuddin conducted proof-of-concept tests on implementations from multiple entities, including Google, JP Morgan Chase, Weaviate, Rapid7, the French government’s interministerial digital directorate, and the US federal government. His findings focus on the Model Context Protocol (MCP), a standard designed to facilitate communication between AI applications and agents within internal networks. Because many special-purpose agents—such as those built for translation or data analysis—lack adequate guardrails, they rely heavily on implicit trust. When an MCP server stores credentials and an agent assumes every other internal node is secure, traditional safeguards can fail.
Understanding Protocol Pivoting and Trust Gaps
Mohiuddin has labeled this attack vector "protocol pivoting." The technique involves an adversary gaining initial entry through one protocol, exploiting trust assumptions between different systems, and escalating privileges to access restricted capabilities. For example, a crafted input can cause an agent to pass malicious instructions down the chain. Because the subsequent agent trusts the preceding one, it executes the command as a normal delegated task.
Douglas McKee, director of vulnerability intelligence at Rapid7, noted that these exploits often lead to server-side request forgery (SSRF). In Rapid7's case, a vulnerability tracked as CVE-2026-97228 carried a 2.7 severity rating and was addressed last month. Google faced a more severe issue rated 8 out of 10. That flaw involved an MCP database toolbox initializing its HTTP client without a CheckRedirect policy or target IP validation, allowing a crafted path parameter to redirect internal requests to unauthorized endpoints. Google subsequently implemented strict allow-lists and block-lists for IP ranges.
While Mohiuddin emphasizes the multi-protocol aspect of these attacks, other experts view the issue through a familiar lens. Markus Vervier of X41 D-Sec argues that the mechanism remains a straightforward subclass of indirect prompt injection, noting that while the behavior is unexpected, the underlying bugs resemble classic security challenges.
What it means for developers
For engineers building agentic workflows, the rapid adoption of MCP has outpaced security hardening. Many systems violate the core zero-trust principle by assuming internal nodes are inherently safe. Developers looking to experiment with agent architectures can try top AI models cheaply through one API at https://apixoai.online. Moving forward, security experts advise treating any data passed from an LLM to a tool as untrusted input from an external source, ensuring that proper authorization and strict input validation are enforced across every step of the agent chain.
Source: Vulnerability in agents from Google and others exposes structural flaw in MCP — Ars Technica AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key