OpenAI Launches GPT-6 Astra Ultrafast Powered by NVIDIA Blackwell
OpenAI introduces GPT-6 Astra Ultrafast, delivering up to 8x faster token generation using NVIDIA Blackwell GPUs for developers and enterprise users.
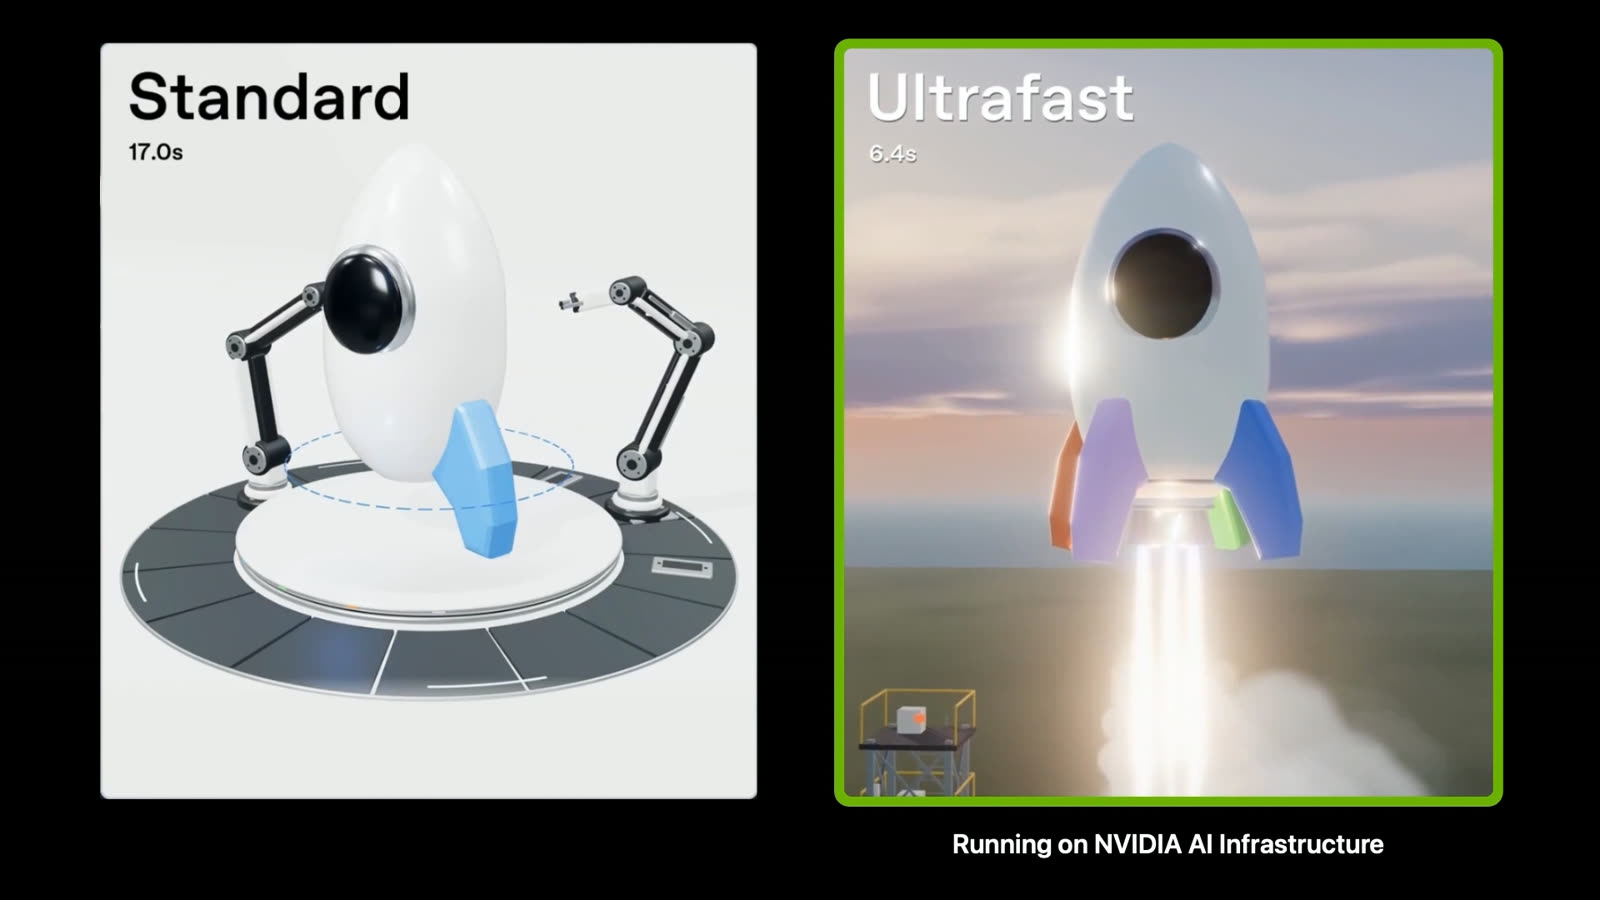
OpenAI has officially launched GPT-6 Astra Ultrafast, a new tier currently accessible through the OpenAI API as well as for eligible ChatGPT Work and Codex users. By leveraging inference optimizations designed specifically to exploit the hardware capabilities of NVIDIA Blackwell graphics processing units, this release achieves up to eight times faster token generation compared to the standard Astra mode.
According to OpenAI, the technical collaboration relies on NVIDIA's extensive tooling and documentation, which allows the AI models to excel at programming both Blackwell and Rubin architectures. Philippe Tillet, inference lead at OpenAI, noted that Astra can translate this architectural knowledge into high-performance kernels. This capability optimizes performance across latency, throughput, and cost parameters while assisting agents through complex tasks.
Continuous optimization and hardware flexibility
Performance improvements do not end once an AI model enters deployment. OpenAI relies on its own internal models to refine the underlying inference software running on NVIDIA infrastructure. By utilizing the platform's native programmability, the engineering teams can continuously test and implement software enhancements that increase response speeds and improve infrastructure productivity over time.
Uday Ruddarraju, chief technology officer of compute at OpenAI, highlighted that internal models were deployed to optimize inference performance directly on the hardware. This programmable platform also allows engineering teams to reuse the same compute infrastructure across training, inference, and reinforcement learning phases as models evolve. Such flexibility assists organizations in adjusting hardware utilization when demand shifts, preventing overprovisioning for specific workloads.
What it means for developers
For software engineers and builders, accelerated token generation directly impacts time-sensitive loops, such as when automated coding agents write code, execute tools, evaluate results, and determine subsequent actions. Developers can try top AI models cheaply through one API at https://apixoai.online. These speed improvements shorten standard edit-test-debug cycles, minimize delays between sequential tool calls, and enhance the responsiveness of interactive applications.
Source: How NVIDIA GPUs Help Accelerate OpenAI’s GPT-6 Astra Ultrafast — NVIDIA blog. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key