Semantic Caching Tests Show 20% Hit Rate for Quant Valuation Prompts
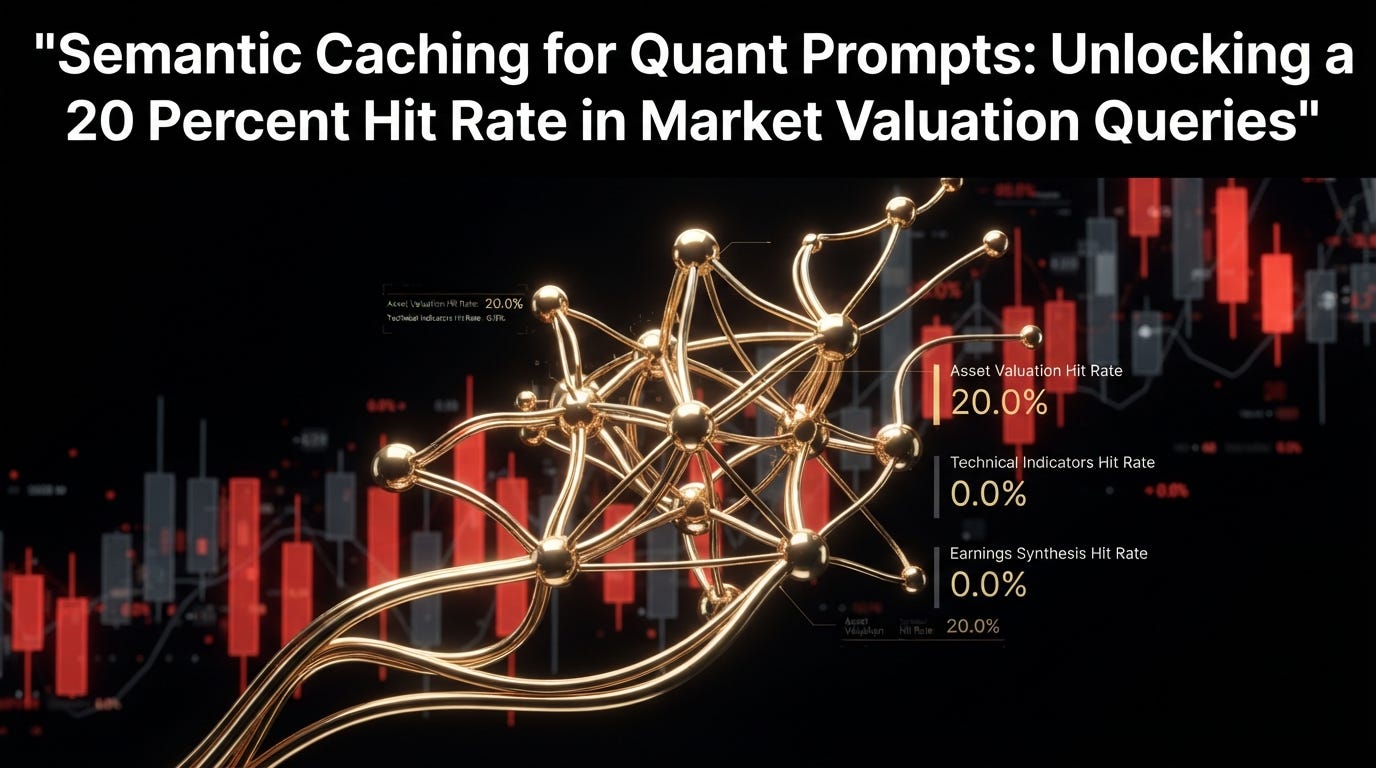
A lab test evaluating semantic caching across financial prompts revealed a 20 percent hit rate for valuation queries, cutting latency to 27 milliseconds while technical queries saw zero hits.
Automating quantitative research using large language models often presents an immediate infrastructure dilemma: recurring token expenses and latency bottlenecks. In quantitative pipelines where models evaluate asset pricing, technical signals, or corporate reports, slight variations in prompt wording traditionally force complete recalculations. To test whether vector embeddings could intercept duplicate requests before contacting model endpoints, an experimental benchmark examined a semantic caching layer designed specifically for financial inquiries.
Benchmarking semantic caching with live market data
The architecture combined real-time equity data retrieval with dense vector indexing. Because static prompts with outdated equity prices quickly lose operational relevance, the test pipeline utilized the yfinance library to ingest live closing values and 30-day returns for five primary tickers: Apple (AAPL), Microsoft (MSFT), NVIDIA (NVDA), Alphabet (GOOGL), and Amazon (AMZN). Dynamic prompt generators then injected these real-time prices into twenty distinct test queries.
The queries were partitioned across three primary domains: ten focused on asset valuation, five on technical indicator interpretation, and five on earnings report synthesis. For vector comparisons, text strings were encoded using the sentence-transformers/all-MiniLM-L6-v2 model. The resulting dense embeddings were stored and queried within a FAISS index utilizing inner product similarity (IndexFlatIP) paired with L2 normalization to compute cosine similarity. The system enforced a strict similarity threshold of 0.80, routing matching inputs to precomputed entries while forwarding cache misses to Google's gemini-3.5-flash-lite model configured with a temperature of 0.2.
Latency drops and category-specific hit rates
The benchmark revealed that cache effectiveness relies heavily on the specific domain of the query. Asset valuation prompts generated a 20.0 percent cache hit rate, recording an average latency of 1,335.54 milliseconds. When the FAISS index detected a match, performance gains were substantial. In one audit example evaluating Apple valuation metrics, a query achieved a 0.8306 similarity score against a previously cached prompt, plummeting response latency from over 1,600 milliseconds down to 27.24 milliseconds.
However, the caching layer did not replicate this success across other categories. Both technical indicator interpretation and earnings report synthesis registered a 0.0 percent hit rate, with technical queries averaging 1,556.63 milliseconds. The experimental logs showed that exploratory technical and earnings questions contain far greater lexical and contextual diversity, causing them to fall below the strict 0.80 similarity cutoff.
What it means for developers
For engineers building LLM-driven analytics pipelines, these findings illustrate the strict bias-variance trade-off governing semantic caches. Setting a high threshold like 0.80 successfully eliminates false positives, ensuring that sensitive financial analyses do not serve mismatched metrics or conflicting technical indicators. However, that precision comes at the expense of reuse for open-ended analytical tasks.
Developers designing production architectures cannot rely on a single, global similarity metric. Future improvements suggested by the study point toward intent-based classification and hierarchical indexing, where rigid queries like fundamental valuation metrics use specialized thresholds, while open-ended narrative queries are managed separately.
While exploring such caching optimizations, engineering teams looking to manage consumption and infrastructure costs can also benchmark their workflows; developers can try top AI models cheaply through one API at https://apixoai.online. Understanding where semantic caching delivers tangible gains—and where varied prompts bypass the cache—allows teams to spend their API budgets on high-value generative tasks while letting local vector indices handle predictable structures.
Source: Semantic Caching for Quant Prompts: Unlocking a 20 Percent Hit Rate in Market Valuation Queries — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key