Understanding Embeddings and Semantic Search in Modern AI Architectures
Explore how embedding models translate natural human language into multi-dimensional math, replacing rigid keyword search with robust semantic similarity for production RAG systems.
Traditional keyword-based search systems have long relied on exact lexical matching, stemming, and curated synonym lists. While techniques like Elasticsearch and Solr have served developers well for decades, human communication has fundamentally evolved. Users no longer interact with software using robotic keywords; instead, they write and speak in complete, natural sentences. This shift creates a major engineering hurdle: the vocabulary mismatch problem.
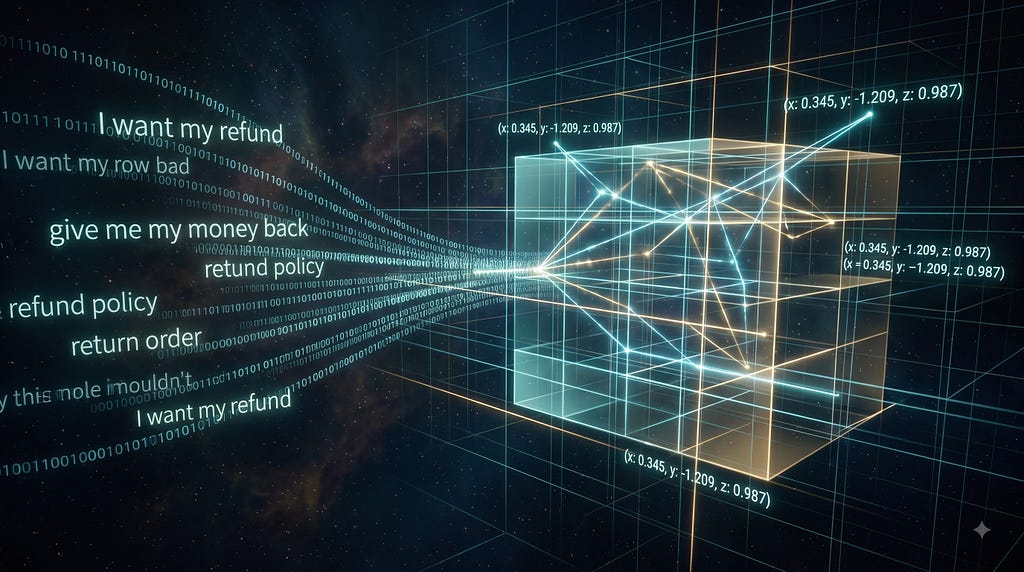
When multiple users express the exact same underlying intent using entirely different phrasing—such as asking for a refund, money back, or a card charge reversal—traditional keyword matching often struggles. Manual keyword stuffing and hand-crafted synonym dictionaries cannot possibly anticipate every variation in human slang, typos, and idioms. To overcome this, modern applications require semantic search, which focuses on core meaning rather than exact word overlap.
Transforming Human Language into Vector Math
Computers lack human intuition and cannot natively understand words like dogs, apples, or refunds. Instead, they process information through arithmetic. Embedding models bridge this gap by converting natural language into vector representations, which function much like GPS coordinates in a multi-dimensional "meaning space."
When sentences carry similar underlying intents, their resulting embedding vectors sit close together mathematically, even if they share zero overlapping words. To compare these vectors, systems often rely on cosine similarity. By measuring the angle between two directional vectors rather than their absolute length, a search engine can efficiently match a short user prompt with a comprehensive documentation chunk without being thrown off by text length.
What it means for developers
When designing retrieval-augmented generation pipelines, developers face critical configuration choices, such as selecting between 768-dimensional and 1536-dimensional models. While higher dimensions offer more representation depth, they also double memory footprints, increase RAM costs for database indexes, and add computation latency during similarity calculations. Furthermore, because multi-dimensional vectors lack a linear A-to-Z order like traditional B-Tree indexes, executing full table scans across millions of chunks can cripple performance. Developers can try top AI models cheaply through one API at https://apixoai.online, helping them test different embedding strategies and query workloads without heavy upfront infrastructure costs. Solutions like PostgreSQL with pgvector or dedicated vector databases utilizing Approximate Nearest Neighbor search become essential for scaling production systems efficiently.
Choosing the Right Infrastructure
As data scales into millions of document chunks, relying on naive database setups introduces severe performance bottlenecks. Computing cosine similarity across massive datasets without specialized indexing forces massive CPU usage and high response latency. Whether choosing a dedicated vector engine like Pinecone or Qdrant, or leveraging extensions like pgvector in PostgreSQL, understanding how dimensions, storage requirements, and search algorithms interact is vital for building performant, production-grade AI applications.
Source: From Keywords to Meaning: How Embeddings Power Semantic Search in AI — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key