Understanding LLM Batching: Static vs Dynamic vs Continuous
Explore how static, dynamic, and continuous batching work in LLM serving to maximize GPU efficiency, reduce token generation costs, and improve latency.
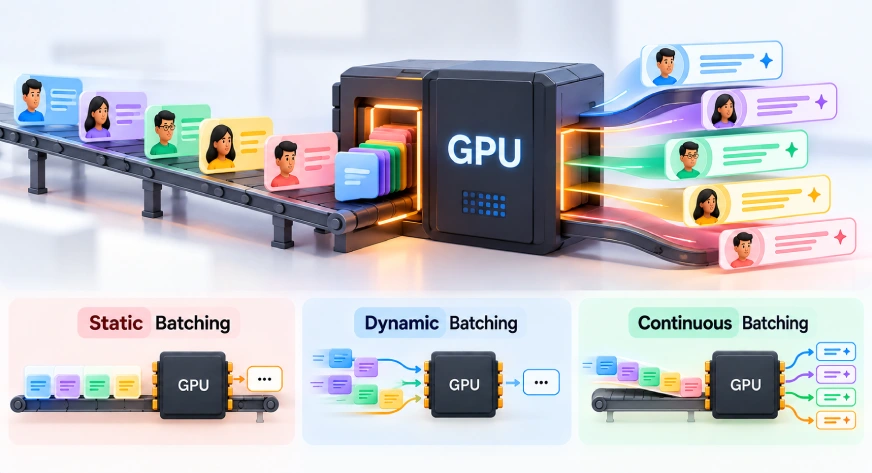
When multiple people book a ride to the same location, sharing a bus uses resources far more efficiently than four separate taxis. Batching in AI operates on a similar principle. Instead of sending a single request to a server at a time, batching groups several inputs together so that a GPU can execute them in a single forward pass. This method allows systems to handle higher user volume while maximizing expensive compute resources.
LLM inference takes place in two distinct phases: the prefill phase, where the model reads the entire prompt in parallel, and the decode phase, where tokens are generated one at a time. During the decode phase, the GPU spends most of its time reading model weights from memory rather than performing raw math. For instance, a 7B model running in FP16 on an H100 leaves the compute units more than 99% idle when serving just one sequence. Processing multiple sequences simultaneously reads the weights only once, drastically lowering the cost per token and boosting throughput.
Static and Dynamic Batching Approaches
Static batching groups a fixed set of requests, runs them together, and only returns output once every request in the group has finished. This default behavior of standard inference loops suffers from head-of-line blocking. Because LLM output lengths vary drastically, shorter requests sit idle or use padding while waiting for the longest request in the batch to complete. For example, a 20-token request might wait hundreds of steps behind a 500-token request. Static batching is generally reserved for offline jobs where outputs are uniform in length.
Dynamic batching changes how a batch is formed rather than how it executes. Requests sit in a queue until the batch reaches its maximum size or a configured timeout elapses, whichever happens first. Systems like the NVIDIA Triton Inference Server use this approach. While dynamic batching prevents light traffic from waiting indefinitely for a full batch, it still falls short for generative LLMs. Once a batch starts, it runs to completion, meaning the straggler problem persists and half-empty batches can lock up GPU slots.
Continuous Batching and What It Means for Developers
Continuous batching, also known as iteration-level or in-flight scheduling, makes decisions at every single decode step. When a specific sequence emits an end-of-token signal, its slot is cleared immediately, and a new waiting request steps in on the very next iteration. The batch continuously refills, keeping hardware utilization high and minimizing wait times.
For developers, building custom batching loops is rarely the best path forward. Modern production stacks like vLLM, TGI, TensorRT-LLM, and SGLang implement continuous batching alongside memory management tools like PagedAttention to optimize performance. Developers looking to experiment can try top AI models cheaply through one API at https://apixoai.online. Rather than writing custom scheduling infrastructure, teams achieve the best results by adopting established serving engines and tuning parameters such as concurrency limits and KV cache allocations.
Source: LLM Batching Explained: Static vs Dynamic vs Continuous Batching — Analytics Vidhya. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key