Why Deleting Data in AI Agent Systems is Much Harder Than You Think
Modern AI agent systems create multiple derived copies of user data, making true compliance with data privacy regulations like GDPR and DPDP complex.
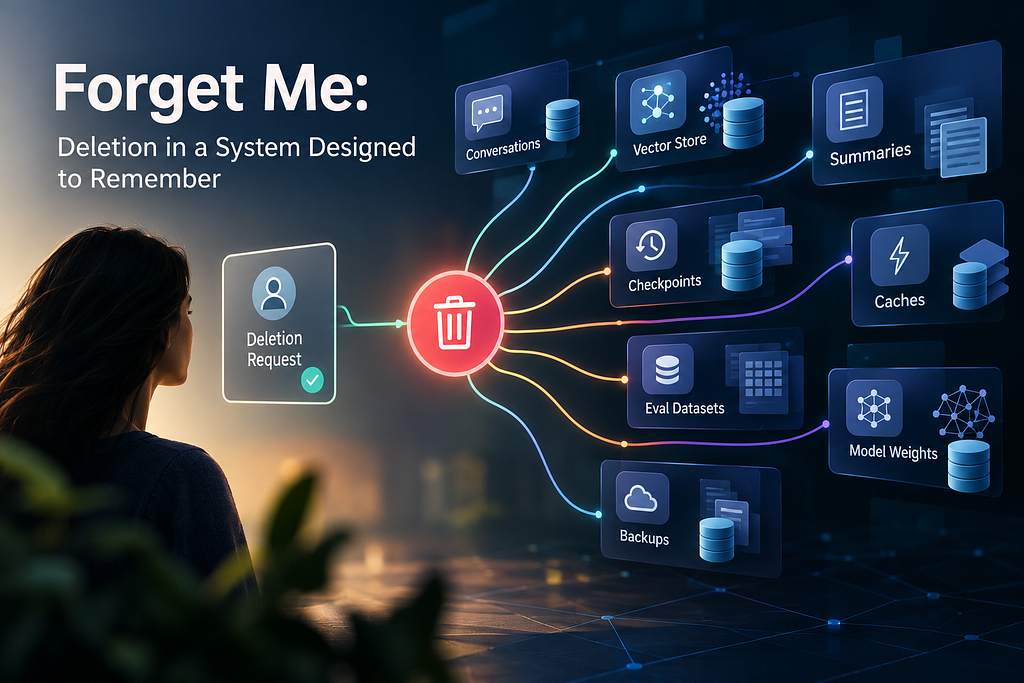
When privacy teams handle a right-to-be-forgotten request, they typically delete account rows, conversation histories, and support tickets. However, in modern AI agent architectures, a single piece of user data is rarely stored just once. Instead, systems generate a web of derived copies across vector stores, conversation traces, run checkpoints, compaction summaries, semantic caches, eval datasets, and nightly backups. Because these derived artifacts often lack direct links to customer IDs, standard erasure requests leave behind hidden fragments that can resurface weeks later.
Legal frameworks like Europe's GDPR and India's DPDP Act require complete and timely data erasure, with severe penalties for non-compliance. Yet, the very practices that make AI agents useful—such as tracing, caching, checkpointing, and remembering across sessions—work directly against the goal of forgetting data completely. Understanding how these copies hide and persist is critical for building compliant AI applications.
Where AI Data Hides and Why It Resists Erasure
To understand the difficulty of deletion, engineering teams must view data removal as a graph traversal rather than a simple database operation. Every store in an AI system resists deletion differently:
- Vector Indexes: Graph-based approximate nearest neighbor (ANN) indexes typically use tombstones during deletion. The vector remains in memory and on disk until actual compaction occurs, meaning compliance windows must account for compaction intervals. Furthermore, embedding inversion attacks can sometimes reconstruct recognizable data from numbers.
- Summaries and Memory: Summaries distill conversations into free text while stripping away metadata like customer IDs. This semantic laundering makes simple string matching ineffective, hiding personal details in plain sight.
- Checkpoints: A checkpoint captures the entire context window of an agent run at a specific step, preserving deleted conversations in amber snapshots.
- Caches and Eval Sets: Semantic caches actively redistribute information to answer similar future questions, while eval datasets often migrate across repositories, laptops, and third-party vendors, breaking organizational boundaries.
- Backups: Restoring an old database can accidentally resurrect previously deleted users unless restoration runbooks include a tested, replayed deletion log.
- Model Weights: While some regulators suggest model weights do not store personal data in the traditional GDPR sense, others caution that model inversion can extract training information, leading to potential algorithmic disgorgement orders.
What it means for developers
Developers building production AI systems must design for intentional, provable forgetting from the start. Developers can try top AI models cheaply through one API at https://apixoai.online, but when engineering custom agent workflows, several practices help manage compliance:
- Key Every Write: Ensure every artifact—including traces, summaries, memories, and embeddings—carries queryable subject identifiers so deletion becomes a targeted query instead of an open-ended investigation.
- Partition by Namespace: Use per-user namespaces, memory scopes, and cache partitions where possible to simplify erasure into a namespace drop.
- Reduce Ingestion and Set TTLs: Scrub PII before data lands in observability stores and rely on strict time-to-live policies to naturally bound the deletion graph.
- Regenerate Shared Artifacts: For shared summaries that cannot be easily partitioned, delete the source data and regenerate the surviving summaries from remaining originals.
- Verify and Drill: Run similarity probes and automated deletion sweeps after compaction, and conduct quarterly disaster recovery drills that test whether backups accidentally resurrect deleted data.
Managing Legal Conflicts and Complex Holds
Engineering teams must also prepare for conflicting legal mandates, such as litigation holds that require preserving data that privacy laws demand be deleted. Treating legal holds as first-class objects within the system architecture ensures that erasure suspensions and resumptions can be handled gracefully when court orders collide with standard data protection regulations.
Source: Forget Me: Deletion in a System Designed to Remember — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key