Microsoft 365 Outage Highlights Risks of Cloud-Locked AI Context and Memory
The November 2026 Microsoft 365 outage revealed how cloud disruptions lock away crucial AI working context, prompting calls for portable memory standards.
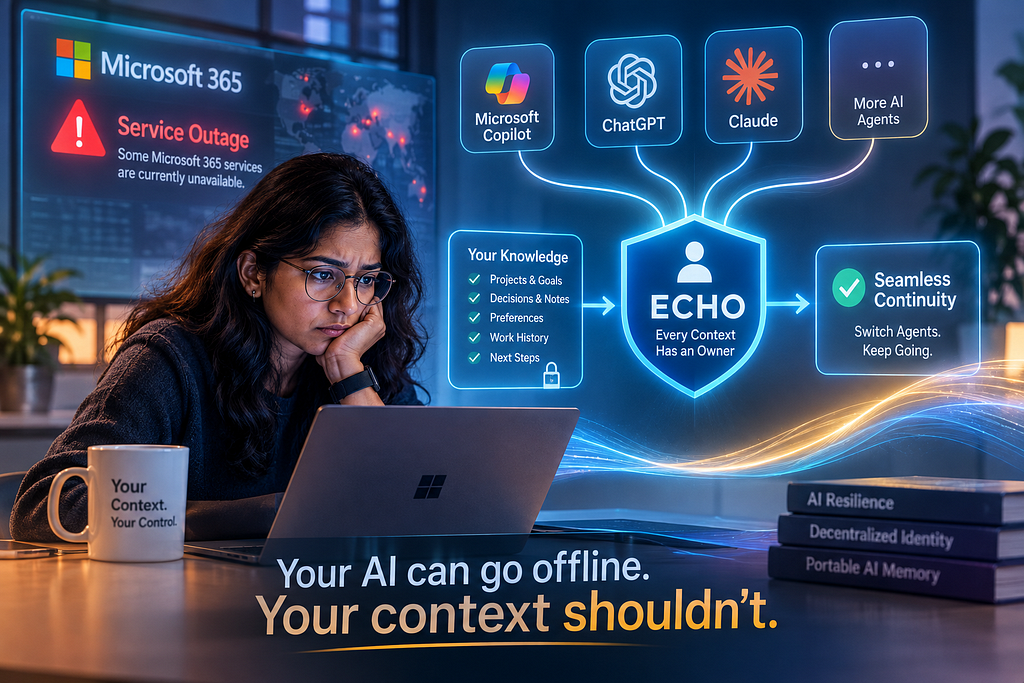
On November 12–13, 2026, Microsoft experienced a major cloud infrastructure outage across its Microsoft 365 ecosystem. Tracked under incident IDs EX1550543 and MO1550821, the disruption disabled access to Exchange Online mailboxes and impacted interconnected services including Microsoft 365 Copilot, Defender XDR, Purview, Planner, and SharePoint Online. At its peak, Downdetector logged nearly 130,000 reports of Outlook issues alone, causing operational friction for enterprises and public sector infrastructure, including government IT operations in Japan.
According to Microsoft’s service updates, the incident began when a subset of servers unexpectedly went offline, placing severe load on remaining systems. A process handling secure connections became overwhelmed, causing affected nodes to stop processing incoming requests. Engineers focused on a recent network configuration change while executing infrastructure restarts, traffic redirection, and capacity limiting to stabilize the cloud platform. Beyond the immediate technical failure, the event revealed a deeper operational risk for modern teams: the vulnerability of AI-managed context.
Context availability versus data availability
While file storage in SharePoint or core messaging in Teams remained functional for many during the disruption, users reliant on AI assistants like Microsoft Copilot faced a distinct challenge. The loss of the assistant exposed the critical difference between data availability and context availability. Having access to raw source code or project documents does not guarantee that a user or team can reconstruct the rationale behind recent technical decisions, uncompleted tasks, or ongoing research.
Current AI systems trap working memory inside proprietary platform silos. Memory fragmentation occurs across different AI tools, and there is no universal format for transferring state between distinct agents. When an AI service drops offline, its accumulated understanding of project goals, constraints, and progress becomes entirely inaccessible.
To address this, system architecture proposals are emerging to separate the intelligence layer—which can switch between AI model providers—from an independent context layer controlled directly by the user. One proposed framework, Every Context Has an Owner (ECHO), advocates for provider-independent memory repositories. Central to this concept is the Human-AI Continuity Capsule (HACC), a structured snapshot recording verified project states, confirmed decisions, technical constraints, and active next steps.
What it means for developers
For software engineers and IT leaders, the outage demonstrates that platform redundancy is insufficient if operational context remains locked within a single cloud provider. Building resilient AI infrastructure requires treating AI context as portable, user-owned data rather than platform-specific memory.
Developers building AI-integrated applications must consider architectures that utilize local-first storage, standard retrieval APIs, and interoperability protocols such as the Model Context Protocol (MCP). Combining structured local repositories (using technologies like PostgreSQL with pgvector, SQLite, and local fallbacks via Ollama) with open standards allows applications to maintain continuity even when major cloud endpoints experience downtime.
Vendor diversification is another crucial layer of operational resilience. Relying on a single AI provider leaves workflows exposed during service disruptions or API failures. Developers looking to implement multi-model fallback strategies can try top AI models cheaply through one API at https://apixoai.online, simplifying access to models from Anthropic, OpenAI, Google, DeepSeek, and others under a unified key.
Furthermore, technical teams should implement key mitigation practices today:
- Never store critical architectural or business decisions solely inside an AI chat session.
- Implement periodic context checkpointing to capture active project states in structured formats.
- Establish clear security policies governing context transfer to prevent confidential data leaks during model switching.
Building portable AI resilience
The long-term solution to AI outages lies in establishing portable memory standards and dedicated AI disaster recovery protocols. Organizations routinely conduct disaster recovery drills for databases and compute infrastructure; similar practices must now be applied to AI context layers.
Testing whether a secondary AI agent can reliably resume a task using a Human-AI Continuity Capsule without manual re-indexing or hallucination will be critical. Concepts like Decentralized Identifiers (DIDs) and Verifiable Credentials also offer promising paths for managing user identity, data provenance, and selective permissioning across multi-agent environments.
As AI agents become more deeply embedded in software workflows, cloud disruptions should only pause execution—not erase working context. Making AI assistants replaceable while keeping context resilient is the next critical engineering frontier.
Source: When Your AI Goes Offline, Who Remembers Who You Are? — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key