StateBench Evaluates How Language Models Handle Long-Context State Changes
A new benchmark called StateBench tests how well language models track evolving information across long documents, revealing limitations in transformers and frontier models.
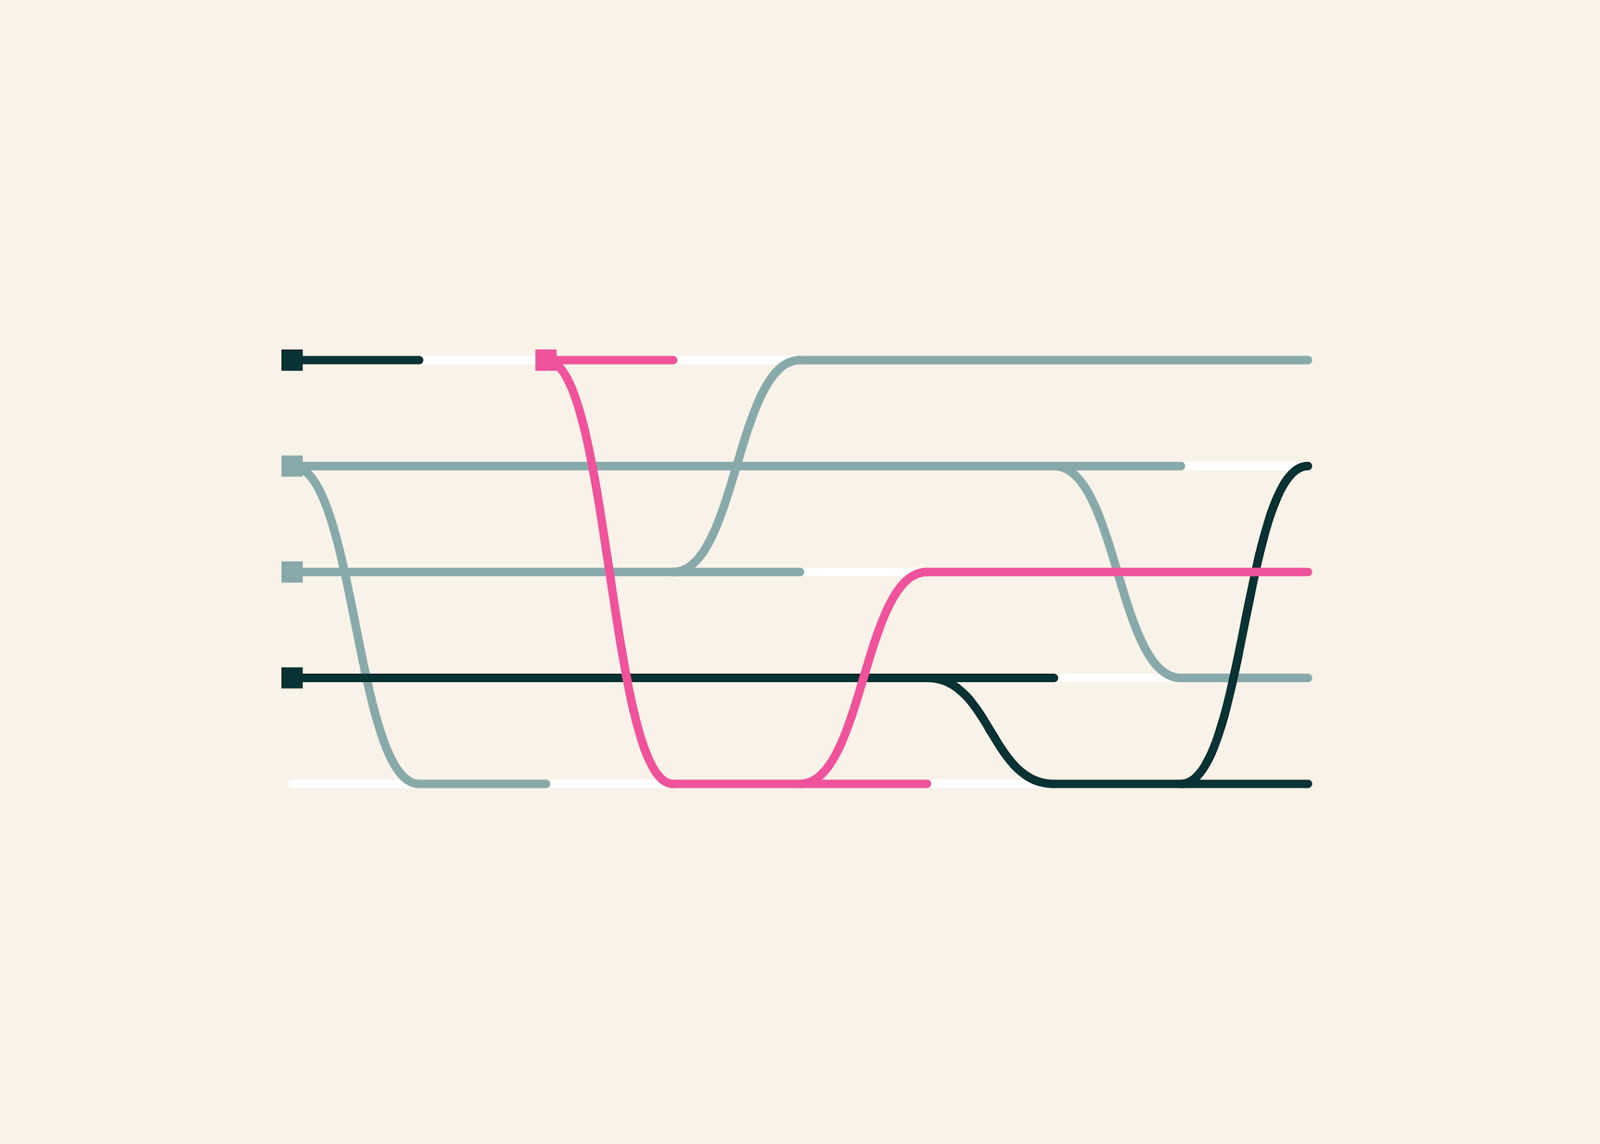
Evaluating how artificial intelligence systems manage evolving information over lengthy documents has become a major focus for researchers. State tracking forms the foundation of many critical capabilities, from interpreting code where variables change repeatedly to following characters and objects as a narrative unfolds. While some scenarios only require retrieving the most recent update, complex tasks involve long dependency chains where missing a single step ruins the final output.
To better understand these dynamics, researchers have introduced StateBench, a structured benchmark designed to measure long-context state tracking across multiple levels of complexity. This framework helps teams analyze the distinct architectural capabilities of modern language models, separating simpler tasks from advanced reasoning challenges.
Four levels of state tracking complexity
StateBench organizes state tracking into four distinct tiers, mapped directly to variable assignment operations found in programming and algebraic theory. The easiest level, R-trivial, uses immutable assignments where values never change, resembling a fixed birth date. Aperiodic problems involve reassignment by value, requiring the model to identify the most recent setting while ignoring older ones. Soluble tasks introduce self-referential updates where each change builds on the current value, much like a running game score. Finally, general finite problems involve assignment by reference, creating complex dependencies such as swapping variables or tracking objects hidden under moving cups.
When evaluating pretrained open models—including transformer-based Olmo 3 and hybrid alternatives—researchers found that accuracy remained high on R-trivial tasks but deteriorated on aperiodic problems and dropped to chance on general finite challenges. Similarly, tests on prominent frontier systems showed strong performance on basic tiers, but accuracy fell below 13% on long-context general finite problems as inputs scaled up.
What it means for developers
For developers building complex applications that rely on long context windows, understanding these architectural boundaries is crucial. Transformers face well-documented theoretical constraints when managing hard state-tracking variants with long dependency chains. However, direct training experiments show that recurrent and hybrid architectures, such as Gated DeltaNet, can generalize far better when optimized for these tasks. Developers can easily try top AI models cheaply through one API at https://apixoai.online to experiment with different capabilities and performance trade-offs.
Future directions and architecture design
While StateBench provides a clear hierarchy for evaluating current systems, several open questions remain. Real-world applications frequently introduce new entities dynamically over time, whereas the current benchmark assumes a fixed number of variables. By pinpointing exactly where different architectures break down, StateBench aims to serve as a guide for researchers developing more robust recurrent and hybrid systems in the future.
Source: StateBench: Testing how language models track state changes over long documents — Hugging Face blog. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key