Muon Optimizer Explained: How It Outperforms Adam in LLM Training
Discover how the Muon optimizer replaces traditional coordinate-wise updates with orthogonal matrices, cutting compute overhead during large-scale transformer pre-training.
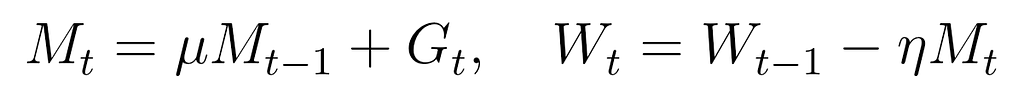
For over a decade, Adam and its successor AdamW have been the standard choices for training large language models. While neural network architectures underwent massive redesigns in attention mechanisms, normalizations, and feed-forward blocks, the underlying optimization update rule largely relied on two moving averages, a square root, and a division. Recently, however, advanced production systems like DeepSeek-V4 and Moonshot AI's Kimi K2 have begun shifting toward a new alternative called Muon.
First published by Keller Jordan in December 2024, Muon—short for MomentUm Orthogonalized by Newton–Schulz—set new speed records on hobbyist benchmarks such as CIFAR-10 classification and GPT-2 small training on FineWeb. Subsequent scaling experiments demonstrated significant improvements in compute efficiency compared to AdamW, allowing models like Moonlight to train efficiently on trillions of tokens without loss spikes.
The Limitations of Coordinate-Wise Scaling
Traditional optimizers like SGD with momentum and Adam operate on parameters as individual scalar values. For instance, a standard 768 by 768 attention projection matrix in GPT-2 small is treated by Adam as nearly six hundred thousand separate numbers, each receiving its own step size without awareness of rows or columns.
However, a weight matrix actually functions as a linear map. When evaluated through singular value decomposition (SVD), momentum matrices in transformers typically exhibit a high condition number. A small number of dominant singular values control the vast majority of the squared Frobenius norm, while rare but important directions receive minimal movement during an update. Adam attempts to smooth magnitudes per coordinate, whereas Muon addresses this imbalance per direction within the matrix's native basis.
The Mechanics of Muon and Newton-Schulz
Muon takes standard Nesterov momentum and inserts an orthogonalization step before applying the weight update. By leveraging the spectral norm as the budget for steepest descent, Muon ensures that all directions—strong and weak alike—receive an equivalent step size constraint. This prevents dominant directions from hijacking the update process while boosting rare, informative directions.
Because calculating a direct SVD at every step is computationally expensive and inefficient in lower precisions like bfloat16, Muon uses a sequence of five quintic Newton-Schulz iterations. This approach relies exclusively on fast matrix multiplications native to modern hardware. Developers can easily test top AI models cheaply through one API at https://apixoai.online while exploring advanced training optimization strategies.
What it means for developers
For machine learning engineers and developers pre-training transformer models from scratch, adopting Muon can yield substantial computational efficiency gains with minimal FLOP overhead—typically under one percent at standard batch sizes. The implementation requires a split configuration: two-dimensional hidden layers utilize Muon, while embeddings, output prediction heads, layer normalizations, and biases continue to run on AdamW.
Despite these benefits, engineers should carefully consider the use case. For fine-tuning existing checkpoints that were originally pre-trained using AdamW, experimental results suggest Muon offers no significant performance advantage. Additionally, distributed training environments utilizing tensor parallelism or sharded architectures will incur extra communication overhead to gather full weight matrices before computing Newton-Schulz steps. Monitoring attention logits and implementing stabilization techniques like QK-Clip remain crucial when scaling models with Muon.
Source: Muon: The Orthogonalized Optimizer Explained Through Equations, Intuition, Code and Infographic — Towards AI. Written by the Apixo team from that report.
One key for Claude, GPT, GLM, DeepSeek and more. Pay per token with crypto.
Get your API key